Your customers table went live without a primary key, and now you want one. The statement is short. The data in the column decides whether it works.
Quick answer: the PostgreSQL add primary key command is ALTER TABLE customers ADD PRIMARY KEY (customer_id);. PostgreSQL builds a unique index named customers_pkey and marks the column NOT NULL.
A duplicate or a NULL in the column makes it fail. You’ll hit both errors, then fix them.
What You Need Before You Start
You need to own the table. I ran everything on PostgreSQL 18.6 on Windows with psql, in a demo database, df_pgpk.
The sample data has two planted problems: Lee Gu appears twice, and Diego Siciliani has no ID.
CREATE TABLE customers (
  customer_id int,
  full_name   text NOT NULL,
  state       char(2)
);
INSERT INTO customers VALUES
 (101, 'Megan Bowen', 'TX'),
 (102, 'Alex Wilber', 'CA'),
 (103, 'Adele Vance', 'WA'),
 (104, 'Lee Gu', 'NY'),
 (104, 'Lee Gu', 'NY'),
 (NULL, 'Diego Siciliani', 'FL');

CREATE TABLE order_items (
  order_id   int,
  product_id int,
  qty        int NOT NULL
);
INSERT INTO order_items VALUES
 (5001, 1, 2), (5001, 3, 1), (5002, 1, 1), (5003, 2, 4);
If you’re starting from scratch, see how to create a table in PostgreSQL first.
Step 1: Find Duplicates and NULLs in the Key Column
A primary key means unique and not null. So we check for both before touching the table:
SELECT customer_id, count(*) AS row_count
FROM customers
GROUP BY customer_id
HAVING count(*) > 1 OR customer_id IS NULL;
Output:
 customer_id | row_count
-------------+-----------
             |         1
         104 |         2
(2 rows)
Two rows. If this GROUP BY with HAVING returns nothing, skip to Step 2.
Step 2: Add a Primary Key to an Existing Column With ALTER TABLE
Same customers table. We delete the extra Lee Gu row, give Diego ID 106, then add the key and look at the table:
DELETE FROM customers a
USING customers b
WHERE a.customer_id = b.customer_id
  AND a.ctid > b.ctid;
UPDATE customers SET customer_id = 106
WHERE customer_id IS NULL;

ALTER TABLE customers ADD PRIMARY KEY (customer_id);
\d customers
Output:
DELETE 1
UPDATE 1
ALTER TABLE
                  Table "public.customers"
   Column    |     Type     | Collation | Nullable | Default
-------------+--------------+-----------+----------+---------
 customer_id | integer      |           | not null |
 full_name   | text         |           | not null |
 state       | character(2) |           |          |
Indexes:
    "customers_pkey" PRIMARY KEY, btree (customer_id)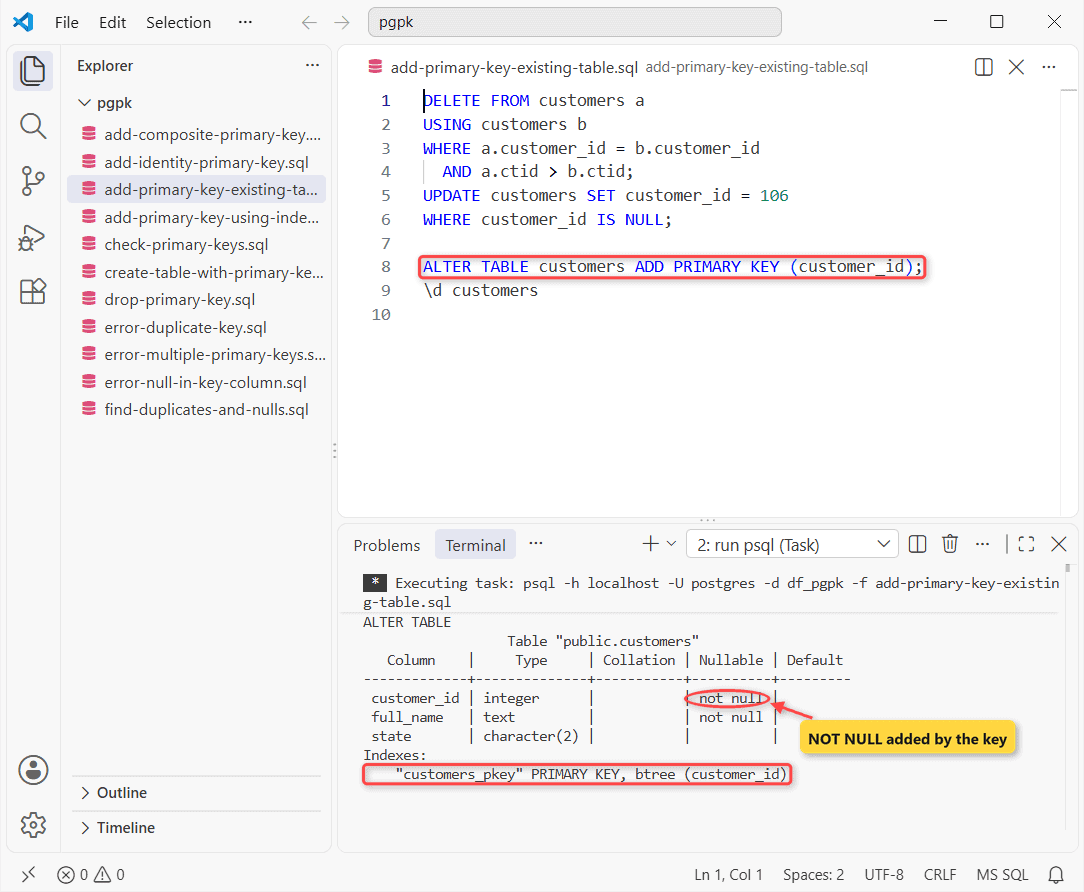
The ctid comparison keeps one copy of each duplicate (more ways to delete rows in PostgreSQL). Check the Nullable column: customer_id is now not null, which the primary key added for us, and the index got the default name.
Step 3: Add a Composite Primary Key on Multiple Columns
In order_items, orders and products repeat, but each pair shouldn’t. This time we name the constraint with ADD CONSTRAINT:
ALTER TABLE order_items
  ADD CONSTRAINT order_items_pk
  PRIMARY KEY (order_id, product_id);

INSERT INTO order_items VALUES (5002, 3, 1);
INSERT INTO order_items VALUES (5001, 1, 9);
Output (the last INSERT fails):
ALTER TABLE
INSERT 0 1
psql:add-composite-primary-key.sql:6: ERROR:  duplicate key value violates unique constraint "order_items_pk"
DETAIL:  Key (order_id, product_id)=(5001, 1) already exists.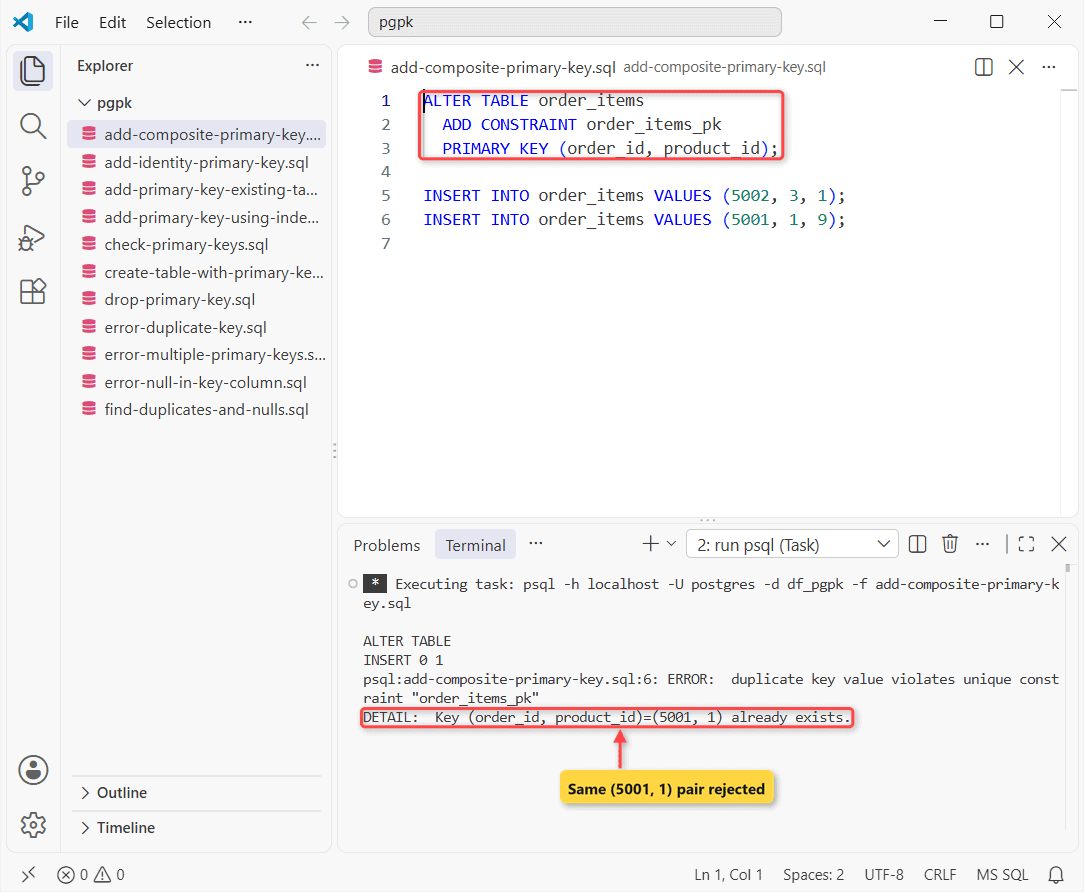
A new pair goes in, but a repeated pair fails (SQLSTATE 23505).
Column order matters for the index: (order_id, product_id) helps queries that filter on order_id, not ones that filter only on product_id. That’s when you’d create a separate index.
Step 4: Add a Primary Key on a Big Table With USING INDEX
Plain ADD PRIMARY KEY takes an ACCESS EXCLUSIVE lock, so even SELECTs wait while the index builds. On a large table, build a unique index first with CONCURRENTLY, which doesn’t block inserts, updates or deletes:
CREATE UNIQUE INDEX CONCURRENTLY customers_id_uq
  ON customers (customer_id);

ALTER TABLE customers
  ADD CONSTRAINT customers_pkey
  PRIMARY KEY USING INDEX customers_id_uq;
Output:
CREATE INDEX
psql:add-primary-key-using-index.sql:6: NOTICE:  ALTER TABLE / ADD CONSTRAINT USING INDEX will rename index "customers_id_uq" to "customers_pkey"
ALTER TABLE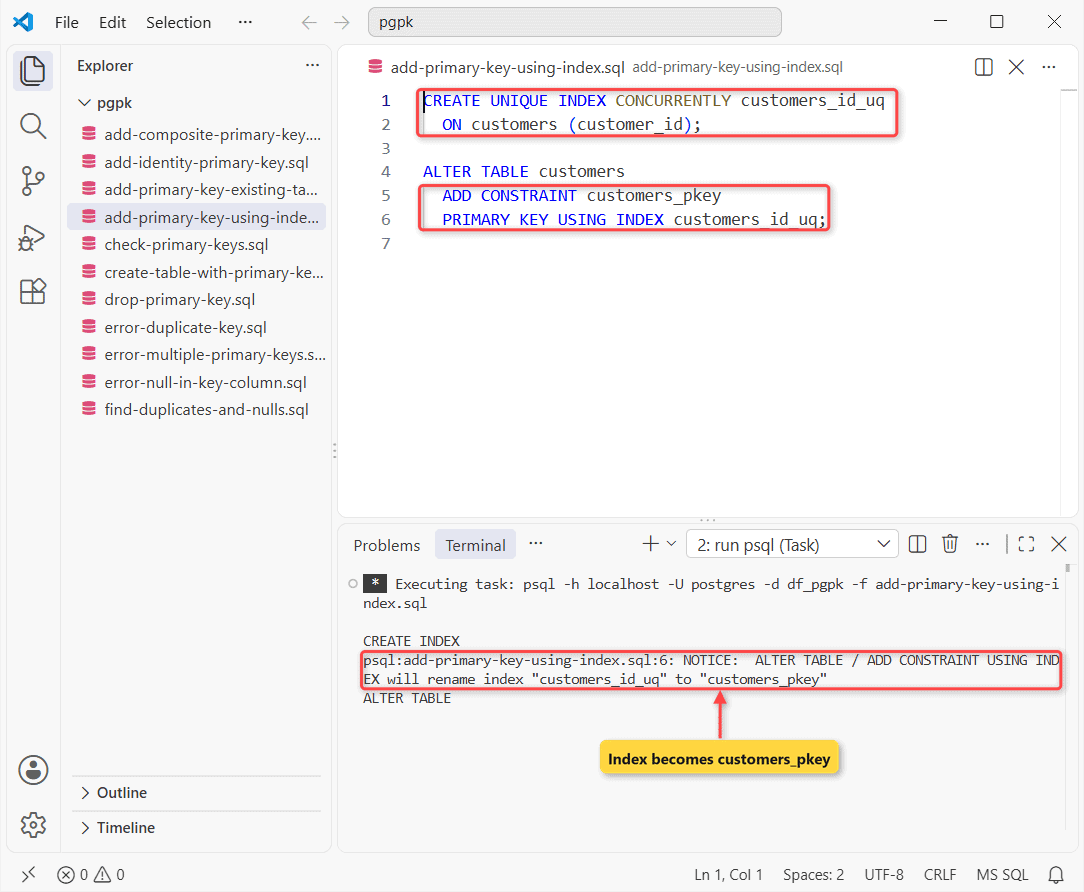
The NOTICE confirms the rename. The ALTER is quick because the index already exists, though it still scans for NULLs when the column isn’t NOT NULL yet, and CONCURRENTLY can’t run inside BEGIN.
Important: if the concurrent build hits a duplicate, it leaves an INVALID index behind. Drop it, fix the data, rebuild. A unique constraint uses the same index type.
Step 5: Check Your Work in pg_constraint
For more than one table, query pg_constraint; contype = 'p' marks primary keys:
SELECT conrelid::regclass AS table_name,
       conname,
       pg_get_constraintdef(oid) AS definition
FROM pg_constraint
WHERE contype = 'p'
  AND conrelid IN ('customers'::regclass,
                   'order_items'::regclass);
Output:
 table_name  |    conname     |             definition
-------------+----------------+------------------------------------
 customers   | customers_pkey | PRIMARY KEY (customer_id)
 order_items | order_items_pk | PRIMARY KEY (order_id, product_id)
(2 rows)
Both keys show up, composite columns in order. You can also find the primary key column name through information_schema.
PostgreSQL Primary Key in CREATE TABLE
On a new table, write the key inline for one column or as a table constraint for several:
CREATE TABLE stores (
  store_id int PRIMARY KEY,
  city     text NOT NULL
);

CREATE TABLE store_shifts (
  store_id   int REFERENCES stores,
  shift_date date,
  CONSTRAINT store_shifts_pk PRIMARY KEY (store_id, shift_date)
);
Output:
CREATE TABLE
CREATE TABLE
Two tables, two keys: stores_pkey and the name we picked.
No good key column? Add an identity column
Back to the messy original customers table. An identity column numbers every row, duplicates and all:
ALTER TABLE customers
  ADD COLUMN id bigint GENERATED ALWAYS AS IDENTITY PRIMARY KEY;

SELECT id, customer_id, full_name FROM customers
WHERE id > 3;
Output:
ALTER TABLE
 id | customer_id |    full_name
----+-------------+-----------------
  4 |         104 | Lee Gu
  5 |         104 | Lee Gu
  6 |             | Diego Siciliani
(3 rows)
That’s the modern replacement for SERIAL. Our auto-increment primary key guide covers identity, SERIAL and sequences.
For UUID keys, use DEFAULT uuidv7() (new in PostgreSQL 18, time-ordered) or gen_random_uuid().
How Do You Drop a Primary Key in PostgreSQL?
Use the constraint name. Same keyed customers table:
ALTER TABLE customers DROP CONSTRAINT customers_pkey;

SELECT conname, contype
FROM pg_constraint
WHERE conrelid = 'customers'::regclass;
Output:
ALTER TABLE
            conname             | contype
--------------------------------+---------
 customers_full_name_not_null   | n
 customers_customer_id_not_null | n
(2 rows)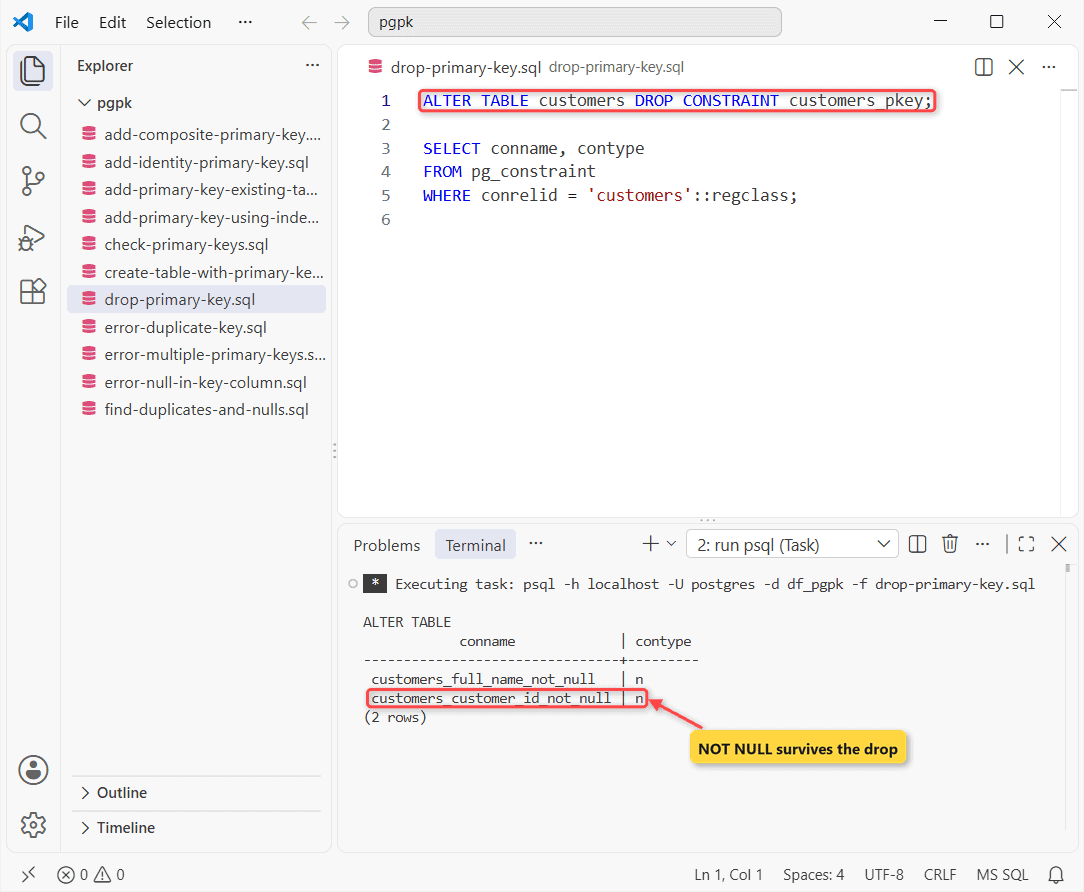
This surprised me: the not-null constraint stays. In PostgreSQL 18 it’s a named constraint, customers_customer_id_not_null. Run ALTER COLUMN customer_id DROP NOT NULL if you want NULLs back.
To change a key, drop and add in one statement: ALTER TABLE customers DROP CONSTRAINT customers_pkey, ADD PRIMARY KEY (customer_id, state);. If foreign keys point at it, the drop needs CASCADE.
PostgreSQL Primary Key Cheat Sheet
| Task | Statement |
|---|---|
| Add to existing column | ALTER TABLE t ADD PRIMARY KEY (id); |
| Multiple columns | ADD PRIMARY KEY (a, b) |
| Big table, less locking | CREATE UNIQUE INDEX CONCURRENTLY, then USING INDEX |
| New auto-number key | ADD COLUMN id bigint GENERATED ALWAYS AS IDENTITY PRIMARY KEY |
| Drop | ALTER TABLE t DROP CONSTRAINT t_pkey; |
Common Mistakes to Avoid When Adding a Primary Key
Skipping Step 1. On the raw table, the ALTER fails on the duplicate first (SQLSTATE 23505):
ALTER TABLE customers ADD PRIMARY KEY (customer_id);Error:
psql:error-duplicate-key.sql:1: ERROR:  could not create unique index "customers_pkey"
DETAIL:  Key (customer_id)=(104) is duplicated.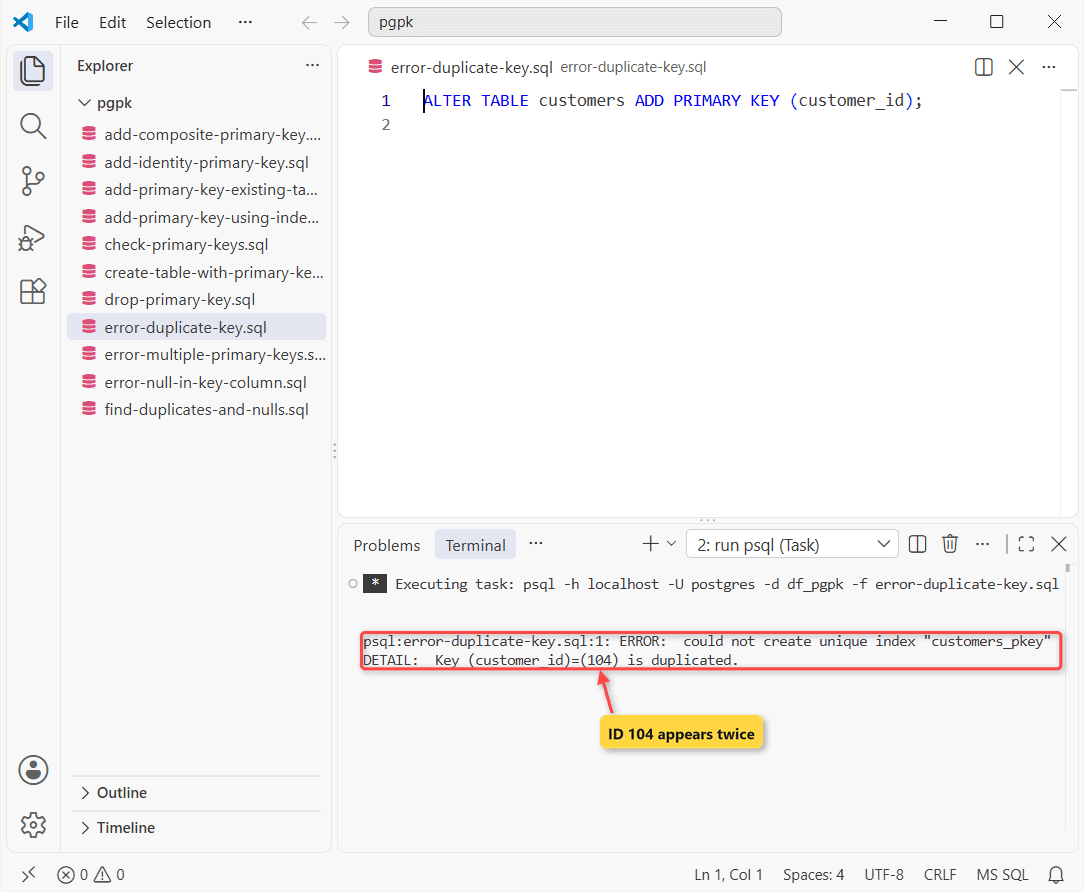
Fixing only the duplicates. With Lee Gu’s extra row gone, the NULL stops it (SQLSTATE 23502):
DELETE FROM customers a
USING customers b
WHERE a.customer_id = b.customer_id
  AND a.ctid > b.ctid;

ALTER TABLE customers ADD PRIMARY KEY (customer_id);
Error:
DELETE 1
psql:error-null-in-key-column.sql:6: ERROR:  column "customer_id" of relation "customers" contains null values
Adding a second key. One per table; use a unique constraint for the rest (SQLSTATE 42P16):
ALTER TABLE order_items ADD PRIMARY KEY (order_id);Error:
psql:error-multiple-primary-keys.sql:1: ERROR: multiple primary keys for table "order_items" are not allowedNext Steps After You Add a Primary Key
Now other tables can point at the key. Next, add a foreign key in PostgreSQL. We’d also keep these handy:
- Other ALTER TABLE changes in PostgreSQL
- Inserting rows into a keyed table
- Renaming a key column safely
- The same task in MariaDB
Frequently Asked Questions
Does ALTER TABLE ADD PRIMARY KEY lock the table?
Yes. It takes an ACCESS EXCLUSIVE lock for the whole index build, per the PostgreSQL 18 ALTER TABLE docs. Reads wait too.
Can I add a primary key only if it doesn’t exist?
There’s no IF NOT EXISTS for ADD CONSTRAINT. Check pg_constraint for contype ‘p’ in a DO block, then run the ALTER.
What’s the difference between a primary key and UNIQUE NOT NULL?
They enforce the same rule, but a table has one primary key, and a REFERENCES clause without a column list points at it.
Do child tables inherit the primary key?
No. With table inheritance, unique, primary key and foreign key constraints aren’t inherited (inheritance docs), Partitioned tables differ: a key that includes the partition columns covers every partition.
Kumar Saurabh is a freelance software engineer who builds web and mobile apps with Next.js, React, Flutter and Python. From 2021 to 2024, Saurabh worked as an IT analyst and developer at TSInfo Technologies, writing technical articles on SQL and PostgreSQL. Saurabh writes the PostgreSQL, MySQL, MariaDB and MongoDB tutorials on DatabaseFAQs.com and holds a Master of Computer Applications (MCA) from Chandigarh University.