
If you need to number rows in a result set, the SQL Server ROW_NUMBER function does it in one line. Put the sort order inside OVER:
SELECT ROW_NUMBER() OVER (ORDER BY Amount DESC) AS RowNum, OrderID, Amount
FROM dbo.Orders;
The trouble starts when you filter on that number, keep one row per group, or add a JOIN. I ran every case below.
Sample Orders Table for ROW_NUMBER
Tested on SQL Server 2025 (17.0.1000.7) Standard Developer, sqlcmd in VS Code. Five customers, nine orders.
Watch the three tied pairs ($975.00, $410.00, $250.00); they’re why the ranking functions disagree later.
CREATE TABLE dbo.Customers (
    CustomerID int          PRIMARY KEY,
    FullName   nvarchar(16) NOT NULL,
    State      char(2)      NOT NULL
);
CREATE TABLE dbo.Orders (
    OrderID    int          PRIMARY KEY,
    CustomerID int          NOT NULL,
    OrderDate  date         NOT NULL,
    Amount     decimal(8,2) NOT NULL
);
INSERT INTO dbo.Customers VALUES
(1, N'Hannah Brooks', 'TX'), (2, N'Tyler Reed', 'CA'),
(3, N'Grace Miller', 'TX'), (4, N'Marcus Bennett', 'NY'),
(5, N'Olivia Hayes', 'CA');
INSERT INTO dbo.Orders VALUES
(101, 1, '2026-01-05', 250.00), (102, 1, '2026-02-11', 180.00),
(103, 2, '2026-01-20', 975.00), (104, 3, '2026-02-02', 250.00),
(105, 3, '2026-03-15', 410.00), (106, 4, '2026-01-28', 975.00),
(107, 2, '2026-03-03', 120.00), (108, 5, '2026-02-19', 640.00),
(109, 1, '2026-03-22', 410.00);
Method 1: ROW_NUMBER() OVER (ORDER BY) (Recommended Start)
Same nine orders, biggest amount first, with OrderID as a tie-breaker:
SET NOCOUNT ON;
SELECT ROW_NUMBER() OVER (ORDER BY Amount DESC, OrderID) AS RowNum,
       OrderID, Amount
FROM dbo.Orders;
Output:
RowNum               OrderID     Amount
-------------------- ----------- ----------
                   1         103     975.00
                   2         106     975.00
                   3         108     640.00
                   4         105     410.00
                   5         109     410.00
                   6         101     250.00
                   7         104     250.00
                   8         102     180.00
                   9         107     120.00
How does this work? SQL Server sorts by Amount DESC, then hands out 1, 2, 3… Order 103 beats 106 only because its OrderID is lower.
The ORDER BY inside OVER is required, and it only drives the numbering. It doesn’t sort the output. It returns bigint, hence sqlcmd’s wide RowNum column.
Method 2: ROW_NUMBER Over PARTITION BY in SQL Server
Add PARTITION BY and the count restarts at 1 for every group. Here’s each customer’s order sequence by date:
SET NOCOUNT ON;
SELECT ROW_NUMBER() OVER (PARTITION BY CustomerID
                          ORDER BY OrderDate) AS OrderSeq,
       CustomerID, OrderID, OrderDate
FROM dbo.Orders;
Output:
OrderSeq             CustomerID  OrderID     OrderDate
-------------------- ----------- ----------- ----------------
                   1           1         101       2026-01-05
                   2           1         102       2026-02-11
                   3           1         109       2026-03-22
                   1           2         103       2026-01-20
                   2           2         107       2026-03-03
                   1           3         104       2026-02-02
                   2           3         105       2026-03-15
                   1           4         106       2026-01-28
                   1           5         108       2026-02-19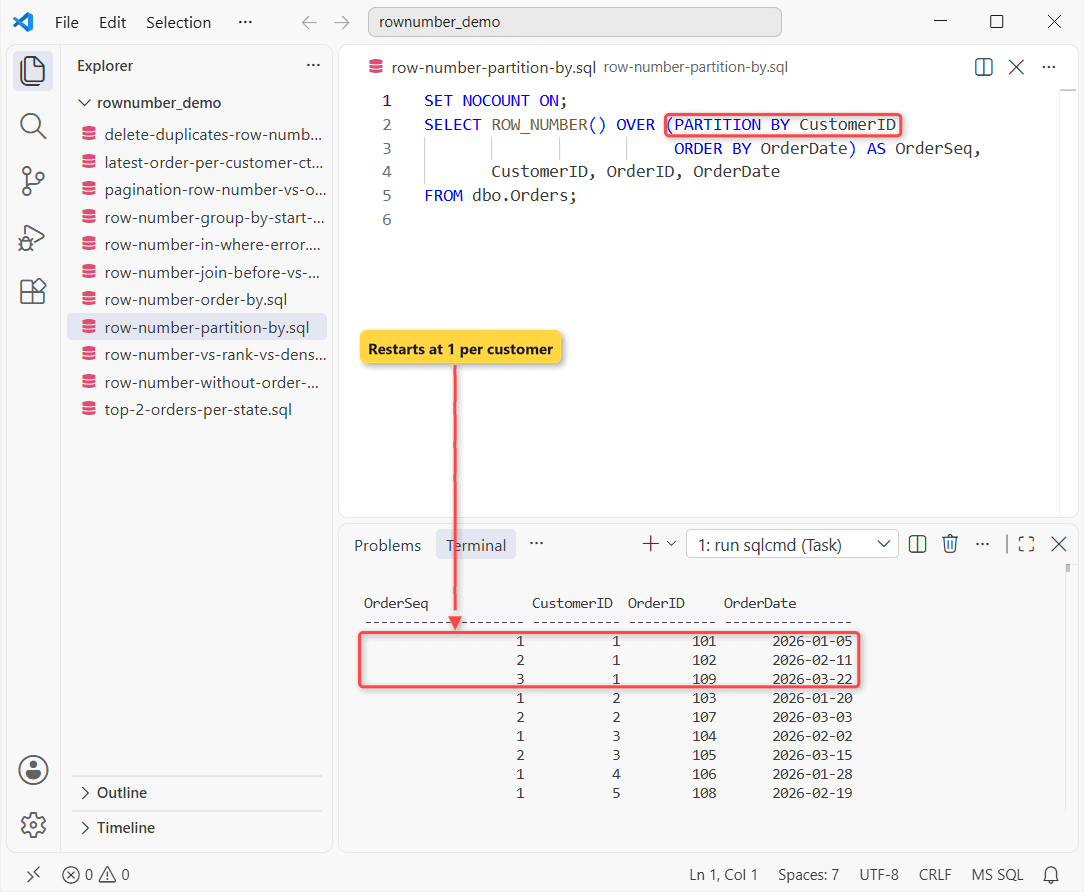
How does this work? Customer 1’s three orders get 1, 2, 3, and customer 2 starts over at 1. If you want a count per customer instead, that’s COUNT with GROUP BY.
Why Can’t You Use ROW_NUMBER in a WHERE Clause?
Everyone tries this first. Both versions fail:
SET NOCOUNT ON;
BEGIN TRY
    EXEC sp_executesql N'SELECT OrderID FROM dbo.Orders
        WHERE ROW_NUMBER() OVER (ORDER BY OrderDate) = 1;';
END TRY
BEGIN CATCH PRINT CONCAT('Msg ', ERROR_NUMBER(), ': ', ERROR_MESSAGE()); END CATCH;

BEGIN TRY
    EXEC sp_executesql N'SELECT ROW_NUMBER() OVER (ORDER BY OrderDate)
        AS RowNum, OrderID FROM dbo.Orders WHERE RowNum = 1;';
END TRY
BEGIN CATCH PRINT CONCAT('Msg ', ERROR_NUMBER(), ': ', ERROR_MESSAGE()); END CATCH;
sqlcmd printed:
Msg 4108: Windowed functions can only appear in the SELECT or ORDER BY clauses.
Msg 207: Invalid column name 'RowNum'.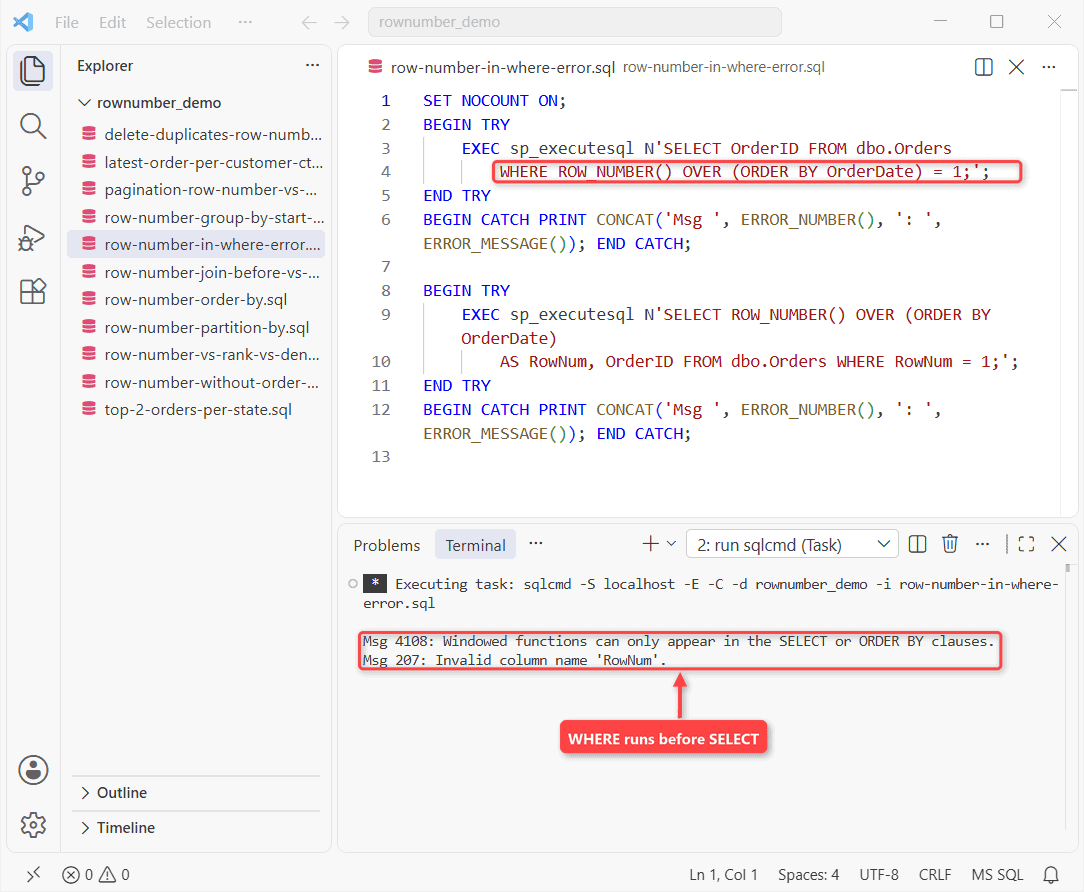
SQL Server evaluates WHERE before SELECT, so the window function and its alias don’t exist yet. You’ll hit the same order rule with INNER JOIN and WHERE. I wrapped each query in sp_executesql so TRY…CATCH could catch the compile error.
Method 3: Filter With a CTE (Latest Order per Customer)
Number the rows inside a CTE, filter outside. Same orders, newest first per customer:
SET NOCOUNT ON;
WITH Ranked AS (
    SELECT CustomerID, OrderID, OrderDate,
           ROW_NUMBER() OVER (PARTITION BY CustomerID
                              ORDER BY OrderDate DESC) AS rn
    FROM dbo.Orders
)
SELECT CustomerID, OrderID, OrderDate
FROM Ranked
WHERE rn = 1;
Result:
CustomerID  OrderID     OrderDate
----------- ----------- ----------------
          1         109       2026-03-22
          2         107       2026-03-03
          3         105       2026-03-15
          4         106       2026-01-28
          5         108       2026-02-19
How does this work? The CTE gives every customer’s newest order rn = 1 and the outer query keeps only those five rows; Hannah’s latest is order 109 on 03/22/2026.
The same pattern is the core of selecting the latest record. If you only need the date, a JOIN on MAX(date) is shorter.
Method 4: Top N per Group With a Derived Table
Change rn = 1 to rn <= 2 for top N per group. The two biggest orders per state:
SET NOCOUNT ON;
SELECT c.State, c.FullName, x.Amount
FROM (
    SELECT o.CustomerID, o.Amount,
           ROW_NUMBER() OVER (PARTITION BY cu.State
                              ORDER BY o.Amount DESC, o.OrderID) AS rn
    FROM dbo.Orders AS o
    JOIN dbo.Customers AS cu ON cu.CustomerID = o.CustomerID
) AS x
JOIN dbo.Customers AS c ON c.CustomerID = x.CustomerID
WHERE x.rn <= 2
ORDER BY c.State, x.Amount DESC;
Output:
State FullName         Amount
----- ---------------- ----------
CA    Tyler Reed           975.00
CA    Olivia Hayes         640.00
NY    Marcus Bennett       975.00
TX    Grace Miller         410.00
TX    Hannah Brooks        410.00
How does this work? The derived table partitions by State and ranks by amount. NY has one order, so it returns one row.
Texas ties at $410.00, and my o.OrderID tie-breaker put Grace's order 105 first. For one matching row per parent, see INNER JOIN with TOP 1.
Method 5: Delete Duplicates and Keep One Row
To remove duplicates with ROW_NUMBER in SQL Server, partition by every column that defines a duplicate. Then delete where rn > 1. My temp table holds five orders plus two copies:
SET NOCOUNT ON;
SELECT CustomerID, OrderDate, Amount INTO #Import
FROM dbo.Orders WHERE CustomerID IN (1, 3);
INSERT INTO #Import SELECT CustomerID, OrderDate, Amount
FROM dbo.Orders WHERE OrderID IN (101, 105);   -- 2 duplicates

WITH d AS (
    SELECT ROW_NUMBER() OVER (PARTITION BY CustomerID, OrderDate, Amount
                              ORDER BY (SELECT NULL)) AS rn
    FROM #Import
)
DELETE FROM d WHERE rn > 1;
PRINT CONCAT(@@ROWCOUNT, ' duplicate rows deleted');

SELECT COUNT(*) AS RowsLeft FROM #Import;
Result:
2 duplicate rows deleted
RowsLeft
-----------
          5
How does this work? Each duplicate pair gets 1, 2, and deleting from the CTE deletes from #Import: seven rows drop to five.
ORDER BY (SELECT NULL) is fine because the copies are identical; otherwise order by a load date so the right one survives. The delete duplicate rows guide compares other methods.
Pagination: ROW_NUMBER vs OFFSET FETCH
Page 2, three rows per page, both ways:
SET NOCOUNT ON;
-- page 2, 3 rows per page
SELECT OrderID, OrderDate FROM (
    SELECT OrderID, OrderDate,
           ROW_NUMBER() OVER (ORDER BY OrderDate) AS rn
    FROM dbo.Orders) AS p
WHERE rn BETWEEN 4 AND 6;

-- same page, OFFSET / FETCH
SELECT OrderID, OrderDate FROM dbo.Orders
ORDER BY OrderDate
OFFSET 3 ROWS FETCH NEXT 3 ROWS ONLY;
Output:
OrderID     OrderDate
----------- ----------------
        104       2026-02-02
        102       2026-02-11
        108       2026-02-19
OrderID     OrderDate
----------- ----------------
        104       2026-02-02
        102       2026-02-11
        108       2026-02-19
Identical rows. I'd use OFFSET/FETCH (SQL Server 2012+) unless the page needs the number itself.
ROW_NUMBER With JOIN: Number Before or After the Join?
Query A numbers the joined, filtered rows. Query B numbers all orders first, then joins to Texas customers:
SET NOCOUNT ON;
-- A: number the JOIN result (after WHERE)
SELECT ROW_NUMBER() OVER (ORDER BY o.OrderDate) AS RowNum,
       c.FullName, o.OrderDate
FROM dbo.Orders AS o
JOIN dbo.Customers AS c ON c.CustomerID = o.CustomerID
WHERE c.State = 'TX';

-- B: number all orders first, then join
WITH n AS (SELECT CustomerID, OrderDate,
           ROW_NUMBER() OVER (ORDER BY OrderDate) AS RowNum
           FROM dbo.Orders)
SELECT n.RowNum, c.FullName, n.OrderDate
FROM n JOIN dbo.Customers AS c ON c.CustomerID = n.CustomerID
WHERE c.State = 'TX';
What came back:
RowNum               FullName         OrderDate
-------------------- ---------------- ----------------
                   1 Hannah Brooks          2026-01-05
                   2 Grace Miller           2026-02-02
                   3 Hannah Brooks          2026-02-11
                   4 Grace Miller           2026-03-15
                   5 Hannah Brooks          2026-03-22
RowNum               FullName         OrderDate
-------------------- ---------------- ----------------
                   1 Hannah Brooks          2026-01-05
                   4 Grace Miller           2026-02-02
                   5 Hannah Brooks          2026-02-11
                   8 Grace Miller           2026-03-15
                   9 Hannah Brooks          2026-03-22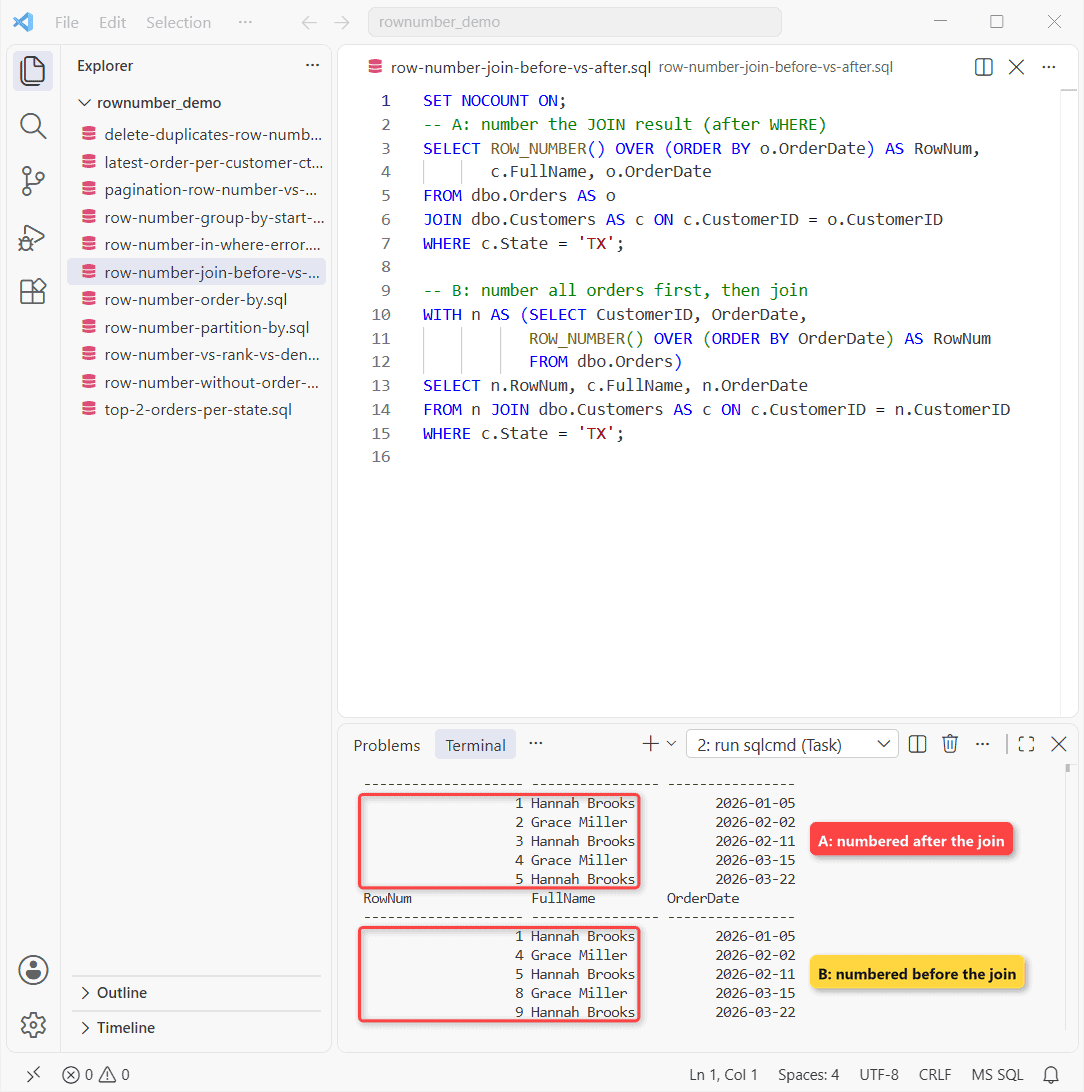
How does this work? In A, WHERE c.State = 'TX' runs before the window function, so the five Texas orders get 1-5. In B, the CTE sees all nine orders, so Grace's 02/02/2026 order is 4th company-wide.
Rows duplicated by a one-to-many INNER JOIN get their own numbers too, so remove them first with DISTINCT in a JOIN.
ROW_NUMBER vs RANK vs DENSE_RANK on Ties
Same orders, no tie-breaker this time:
SET NOCOUNT ON;
SELECT OrderID, Amount,
       ROW_NUMBER() OVER (ORDER BY Amount DESC) AS RowNum,
       RANK()       OVER (ORDER BY Amount DESC) AS Rnk,
       DENSE_RANK() OVER (ORDER BY Amount DESC) AS DenseRnk
FROM dbo.Orders;
Output:
OrderID     Amount     RowNum               Rnk                  DenseRnk
----------- ---------- -------------------- -------------------- --------------------
        103     975.00                    1                    1                    1
        106     975.00                    2                    1                    1
        108     640.00                    3                    3                    2
        109     410.00                    4                    4                    3
        105     410.00                    5                    4                    3
        104     250.00                    6                    6                    4
        101     250.00                    7                    6                    4
        102     180.00                    8                    8                    5
        107     120.00                    9                    9                    6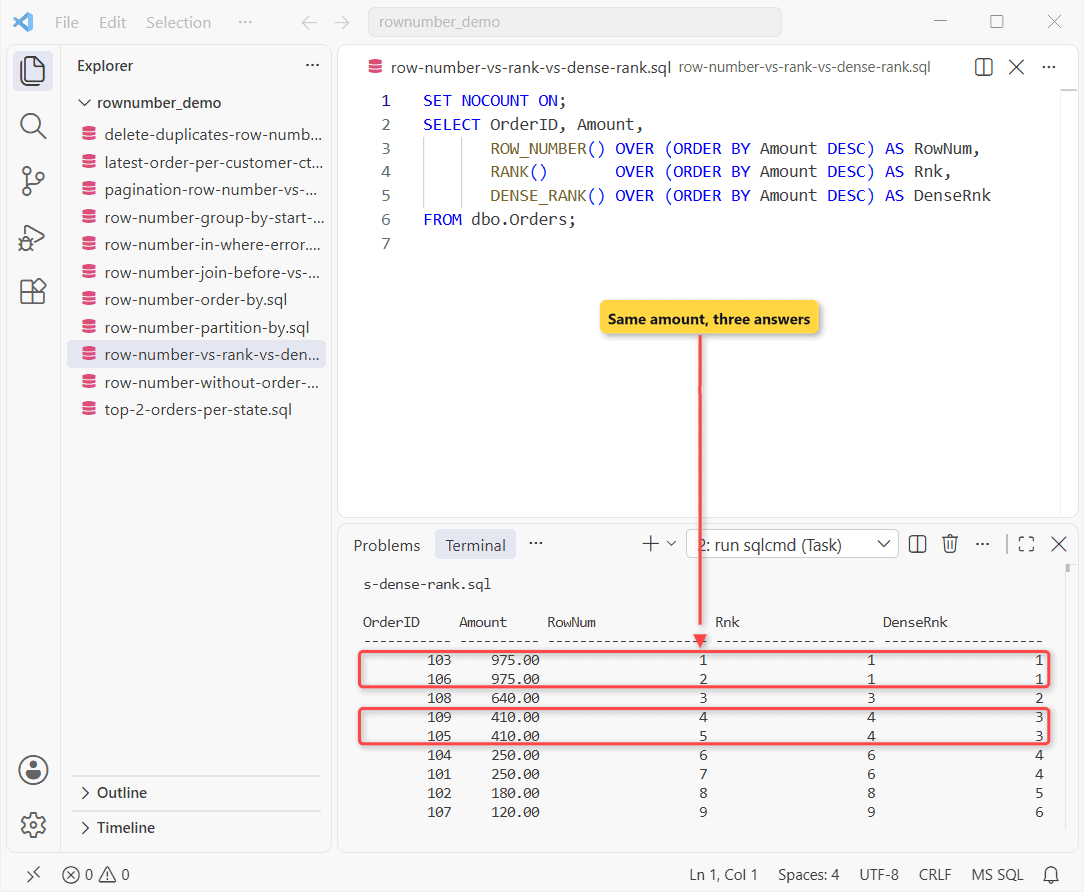
| Function | Ties at $975.00 | Next value | Use it for |
|---|---|---|---|
| ROW_NUMBER | 1, 2 | 3 | one row per group, paging, dedupe |
| RANK | 1, 1 | 3 (gap) | competition ranking |
| DENSE_RANK | 1, 1 | 2 | "top 3 distinct amounts" |
Look at the $410.00 pair: with the OrderID tie-breaker, 105 came first, but without it this run put 109 first. That's why Microsoft calls ROW_NUMBER nondeterministic.
Important: if you page or dedupe on a tied column, you can get a different row each run. PostgreSQL's RANK function splits ties the same way.
Variations: No ORDER BY, a Custom Start Value, GROUP BY
Leaving out ORDER BY fails; ORDER BY (SELECT NULL) is the workaround:
SET NOCOUNT ON;
BEGIN TRY
    EXEC sp_executesql N'SELECT ROW_NUMBER() OVER () AS RowNum
        FROM dbo.Orders;';
END TRY
BEGIN CATCH PRINT CONCAT('Msg ', ERROR_NUMBER(), ': ', ERROR_MESSAGE()); END CATCH;

SELECT TOP (3) ROW_NUMBER() OVER (ORDER BY (SELECT NULL)) AS RowNum,
       OrderID
FROM dbo.Orders;
sqlcmd printed:
Msg 4112: The function 'ROW_NUMBER' must have an OVER clause with ORDER BY.
RowNum               OrderID
-------------------- -----------
                   1         101
                   2         102
                   3         103
That isn't insert order. It's scan order, with no guarantee.
Start at 1001 by adding 1000. Window functions run after GROUP BY, so you can rank totals too:
SET NOCOUNT ON;
SELECT 1000 + ROW_NUMBER() OVER (ORDER BY SUM(o.Amount) DESC) AS RankNo,
       c.FullName, CAST(SUM(o.Amount) AS decimal(8,2)) AS Total
FROM dbo.Orders AS o
JOIN dbo.Customers AS c ON c.CustomerID = o.CustomerID
GROUP BY c.FullName;
Output:
RankNo               FullName         Total
-------------------- ---------------- ----------
                1001 Tyler Reed          1095.00
                1002 Marcus Bennett       975.00
                1003 Hannah Brooks        840.00
                1004 Grace Miller         660.00
                1005 Olivia Hayes         640.00
Tyler's $1,095.00 puts him at 1001. For per-customer counts, see LEFT JOIN with COUNT.
Things to Keep in Mind
- Add the primary key as a tie-breaker in
OVER (ORDER BY ...). - Filter on the number in a CTE or derived table; WHERE gives Msg 4108.
- Number after the JOIN for per-filter numbers, before it for global positions.
- ROW_NUMBER isn't stored; use IDENTITY or a SEQUENCE for a permanent number.
Next step: practice the same ideas in PostgreSQL ROW_NUMBER, where the syntax matches.
A few related reads:
Frequently Asked Questions
Can I use ROW_NUMBER without PARTITION BY?
Yes. PARTITION BY is optional; without it SQL Server numbers the whole result set as one group. ORDER BY is the only required part, per the ROW_NUMBER (Transact-SQL) reference.
Can I add ROWS BETWEEN to ROW_NUMBER?
No. The ROWS and RANGE frame options of the OVER clause aren't allowed with ROW_NUMBER. Frames only matter for aggregates such as SUM() OVER for running totals.
How do I join two tables on ROW_NUMBER?
Number each table in its own CTE, then join on the two row-number columns (a.rn = b.rn). That pairs rows by position, so give both OVER clauses a unique ORDER BY or the pairs can change between runs.
Does ROW_NUMBER work in Azure SQL Database?
Yes. Azure SQL Database, Azure SQL Managed Instance, Azure Synapse Analytics and Microsoft Fabric support it with the same syntax as SQL Server.
Shivam Dogra is a cloud database developer and Team Lead at TSInfo Technologies, where he has worked since June 2021. He writes the SQL Server and Oracle tutorials on DatabaseFAQs.com, covering queries, joins, stored procedures, triggers and permissions. Shivam holds a Master of Computer Applications (MCA) from Chandigarh University.