
If you’ve chained one more table onto a report and watched the totals double, the joins did exactly what you wrote. PostgreSQL multiple joins are JOIN … ON clauses stacked in one FROM, each joining the next table to the rows built so far:
SELECT o.order_id, c.name AS customer, e.name AS rep
FROM orders o
JOIN customers c ON c.customer_id = o.customer_id
JOIN employees e ON e.emp_id = o.rep_id
ORDER BY o.order_id;
On PostgreSQL 18.6 (x86_64-windows, run from psql), that returns all five orders with the customer and the sales rep:
 order_id |    customer    |      rep
----------+----------------+---------------
     1001 | Hannah Brooks  | Kevin Doyle
     1002 | Tyler Reed     | Laura Simmons
     1003 | Hannah Brooks  | Kevin Doyle
     1004 | Grace Miller   | Brian Foster
     1005 | Marcus Bennett | Laura Simmons
(5 rows)
My verdict after running every pattern below: INNER JOIN chains are safe, and the planner reorders them anyway. Wrong answers come from a WHERE on a left-joined table, an INNER JOIN after a LEFT JOIN, or two one-to-many tables in one query.
The sample tables for these PostgreSQL joins
Six small tables in a pgjoins_demo database. Olivia Grant has no orders, orders 1003 and 1005 have no payments, and order 1001 was paid in two installments. Each of those rows breaks a join somewhere below.
CREATE TABLE employees (
  emp_id int PRIMARY KEY, name varchar(20), manager_id int);
INSERT INTO employees VALUES
 (1,'Rachel Turner',NULL), (2,'Kevin Doyle',1),
 (3,'Laura Simmons',1), (4,'Brian Foster',2);
CREATE TABLE customers (
  customer_id int PRIMARY KEY, name varchar(20), state char(2));
INSERT INTO customers VALUES
 (1,'Hannah Brooks','TX'), (2,'Tyler Reed','CO'), (3,'Grace Miller','WA'),
 (4,'Marcus Bennett','TX'), (5,'Olivia Grant','MA');
CREATE TABLE orders (
  order_id int PRIMARY KEY, customer_id int REFERENCES customers,
  rep_id int REFERENCES employees, order_date date, status varchar(10));
INSERT INTO orders VALUES
 (1001,1,2,'2026-09-14','Shipped'), (1002,2,3,'2026-09-22','Shipped'),
 (1003,1,2,'2026-10-03','Pending'), (1004,3,4,'2026-10-09','Shipped'),
 (1005,4,3,'2026-10-21','Canceled');
CREATE TABLE products (
  product_id int PRIMARY KEY, name varchar(15), price numeric(8,2));
INSERT INTO products VALUES
 (1,'Standing Desk',389.00), (2,'Monitor Arm',79.50),
 (3,'Desk Lamp',42.00), (4,'Office Chair',249.00);
CREATE TABLE order_items (
  order_id int REFERENCES orders, product_id int REFERENCES products, qty int);
INSERT INTO order_items VALUES
 (1001,1,1), (1001,2,2), (1002,4,1), (1003,3,2),
 (1004,1,1), (1004,3,1), (1005,2,1);
CREATE TABLE payments (
  payment_id int PRIMARY KEY, order_id int REFERENCES orders, amount numeric(8,2));
INSERT INTO payments VALUES
 (1,1001,300.00), (2,1001,248.00), (3,1002,249.00), (4,1004,431.00);
ANALYZE;
If you’re building your own, the foreign keys in PostgreSQL guide explains the REFERENCES clauses, and inserting multiple rows covers the INSERT syntax.
Join 3 or more tables in PostgreSQL with INNER JOIN
You add a fourth table the same way you added the third: one more JOIN, one more ON. Here the same sample tables answer “what did my Texas customers buy?” through the order_items bridge table:
SELECT c.name, o.order_id, p.name AS product, i.qty
FROM customers c
JOIN orders o      ON o.customer_id = c.customer_id
JOIN order_items i ON i.order_id = o.order_id
JOIN products p    ON p.product_id = i.product_id
WHERE c.state = 'TX'
ORDER BY o.order_id, p.name;
Output:
      name      | order_id |    product    | qty
----------------+----------+---------------+-----
 Hannah Brooks  |     1001 | Monitor Arm   |   2
 Hannah Brooks  |     1001 | Standing Desk |   1
 Hannah Brooks  |     1003 | Desk Lamp     |   2
 Marcus Bennett |     1005 | Monitor Arm   |   1
(4 rows)
That’s 4 rows: three for Hannah Brooks, one for Marcus Bennett.
How does this work?
Each ON links the new table to a table already in the FROM. order_items sits between orders and products because one order holds many products and one product appears on many orders (a many-to-many bridge).
A data-warehouse star join is the same thing with one fact table in the middle and every dimension joined to it; a snowflake adds a second hop (product to category to department). For the two-table basics, start with PostgreSQL joins.
Join the same table twice with aliases (self join)
Same orders table, but now each order needs the sales rep AND the rep’s manager. Both live in employees, so it joins twice under two aliases:
SELECT o.order_id, rep.name AS rep, mgr.name AS manager
FROM orders o
JOIN employees rep     ON rep.emp_id = o.rep_id
LEFT JOIN employees mgr ON mgr.emp_id = rep.manager_id
ORDER BY o.order_id;
Output:
 order_id |      rep      |    manager
----------+---------------+---------------
     1001 | Kevin Doyle   | Rachel Turner
     1002 | Laura Simmons | Rachel Turner
     1003 | Kevin Doyle   | Rachel Turner
     1004 | Brian Foster  | Kevin Doyle
     1005 | Laura Simmons | Rachel Turner
(5 rows)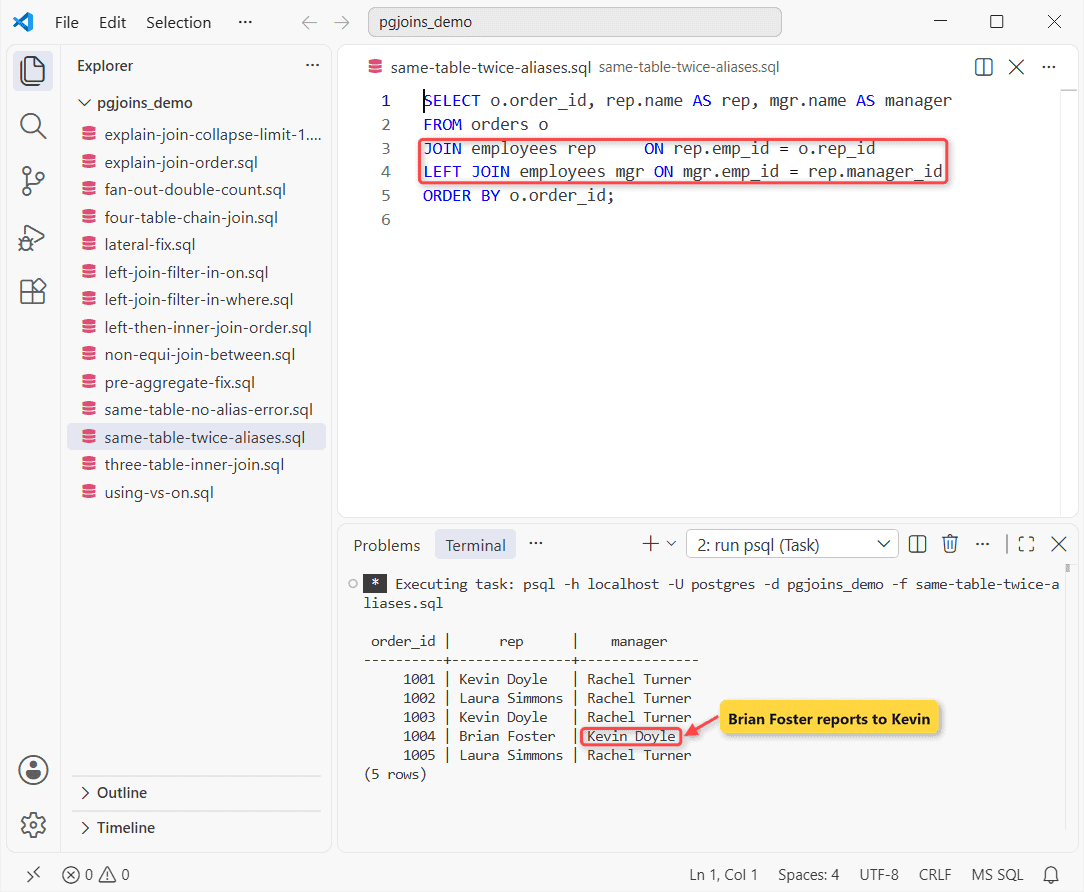
How does this work?
rep and mgr are two independent copies of employees. The second ON uses rep.manager_id, so it walks one level up the org chart. I made it a LEFT JOIN so a rep without a manager wouldn’t vanish.
Skip the aliases and PostgreSQL refuses before running anything:
SELECT orders.order_id, employees.name
FROM orders
JOIN employees ON employees.emp_id = orders.rep_id
JOIN employees ON employees.emp_id = employees.manager_id;
Output and error:
psql:same-table-no-alias-error.sql:4: ERROR: table name "employees" specified more than onceThat’s SQLSTATE 42712. The self join walk-through shows the same idea in SQL Server.
USING vs ON when you join multiple tables
USING (customer_id) is shorthand for ON o.customer_id = c.customer_id, with one difference I care about: the output gets one customer_id column instead of two. With ON, an unqualified name fails:
SELECT * FROM orders JOIN customers USING (customer_id)
WHERE order_id = 1004;

SELECT customer_id FROM orders o
JOIN customers c ON c.customer_id = o.customer_id;
Output and error:
 customer_id | order_id | rep_id | order_date | status  |     name     | state
-------------+----------+--------+------------+---------+--------------+-------
           3 |     1004 |      4 | 2026-10-09 | Shipped | Grace Miller | WA
(1 row)

psql:using-vs-on.sql:5: ERROR:  column reference "customer_id" is ambiguous
LINE 1: SELECT customer_id FROM orders o
               ^
The first query printed customer_id once, as the first column. The second hit SQLSTATE 42702 because both tables still expose the column.
Use USING when the key names match; you need ON when they differ (rep_id to emp_id) or the test isn’t equality.
Join on a range instead of equality
The old inner-join version of this page had a pricing-tier join. Here it is on the same products, with BETWEEN in the ON clause:
WITH price_tiers (tier, lo, hi) AS (VALUES
 ('Budget',0,99.99), ('Mid',100,299.99), ('Premium',300,9999))
SELECT p.name, p.price, t.tier
FROM products p
JOIN price_tiers t ON p.price BETWEEN t.lo AND t.hi
ORDER BY p.price;
Output:
     name      | price  |  tier
---------------+--------+---------
 Desk Lamp     |  42.00 | Budget
 Monitor Arm   |  79.50 | Budget
 Office Chair  | 249.00 | Mid
 Standing Desk | 389.00 | Premium
(4 rows)
Every product lands in exactly one tier because the ranges don’t overlap. Overlapping ranges would duplicate products, so check them with a GROUP BY count first.
Mixing INNER JOIN and LEFT JOIN: where rows silently disappear
Two traps here, and neither raises an error.
A WHERE on the left-joined table turns it into an inner join
You want every customer, plus their shipped orders if any. Same customers and orders:
SELECT c.name, o.order_id, o.status
FROM customers c
LEFT JOIN orders o ON o.customer_id = c.customer_id
WHERE o.status = 'Shipped';
Output:
     name      | order_id | status
---------------+----------+---------
 Hannah Brooks |     1001 | Shipped
 Tyler Reed    |     1002 | Shipped
 Grace Miller  |     1004 | Shipped
(3 rows)
Now the same test moved into ON:
SELECT c.name, o.order_id, o.status
FROM customers c
LEFT JOIN orders o ON o.customer_id = c.customer_id
                  AND o.status = 'Shipped';
Output:
      name      | order_id | status
----------------+----------+---------
 Hannah Brooks  |     1001 | Shipped
 Tyler Reed     |     1002 | Shipped
 Grace Miller   |     1004 | Shipped
 Marcus Bennett |          |
 Olivia Grant   |          |
(5 rows)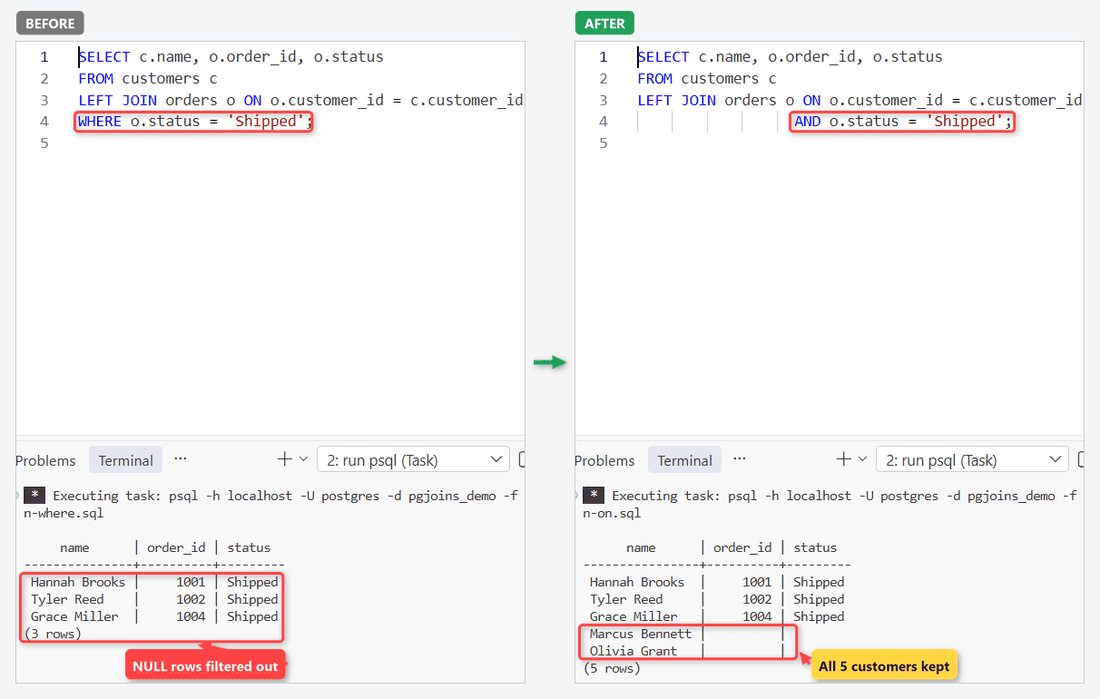
How does this work?
The PostgreSQL docs put it plainly: an ON restriction runs before the join, a WHERE restriction after it. Marcus Bennett and Olivia Grant come out of the LEFT JOIN with NULL status, and NULL = 'Shipped' isn’t true, so WHERE throws them away.
If your condition filters the optional table, put it in ON; keep it in WHERE only when it filters the preserved one (c.state = 'TX'). The PostgreSQL WHERE clause guide covers the NULL rules behind this.
An INNER JOIN after a LEFT JOIN, and what parentheses change
Same five customers, with payments added three ways. If you count rows instead of listing them, the difference is obvious:
SELECT count(*) AS left_then_inner
FROM customers c
LEFT JOIN orders o ON o.customer_id = c.customer_id
JOIN payments pay ON pay.order_id = o.order_id;

SELECT count(*) AS left_then_left
FROM customers c
LEFT JOIN orders o ON o.customer_id = c.customer_id
LEFT JOIN payments pay ON pay.order_id = o.order_id;

SELECT count(*) AS parenthesized
FROM customers c
LEFT JOIN (orders o JOIN payments pay
           ON pay.order_id = o.order_id)
  ON o.customer_id = c.customer_id;
Output:
 left_then_inner
-----------------
               4
(1 row)

 left_then_left
----------------
              7
(1 row)

 parenthesized
---------------
             6
(1 row)
4, 7 and 6 rows. JOIN clauses nest left to right, so the first INNER JOIN filters the LEFT JOIN’s whole result, NULL rows included. Parentheses change the nesting: orders and payments pair up first, then the customers LEFT JOIN wraps the result.
Rule of thumb: once a chain has a LEFT JOIN, every later table that hangs off the optional side should be a LEFT JOIN too, unless you mean the parenthesized version.
Why do totals double when I join multiple tables in PostgreSQL?
Same orders again. Order 1001 has 2 items and 2 payments; order 1004 has 2 items and 1 payment. Join both children at once and sum:
SELECT o.order_id,
       sum(p.price * i.qty) AS items_total,
       sum(pay.amount)      AS paid
FROM orders o
JOIN order_items i ON i.order_id = o.order_id
JOIN products p    ON p.product_id = i.product_id
JOIN payments pay  ON pay.order_id = o.order_id
GROUP BY o.order_id ORDER BY o.order_id;
Output:
 order_id | items_total |  paid
----------+-------------+---------
     1001 |     1096.00 | 1096.00
     1002 |      249.00 |  249.00
     1004 |      431.00 |  862.00
(3 rows)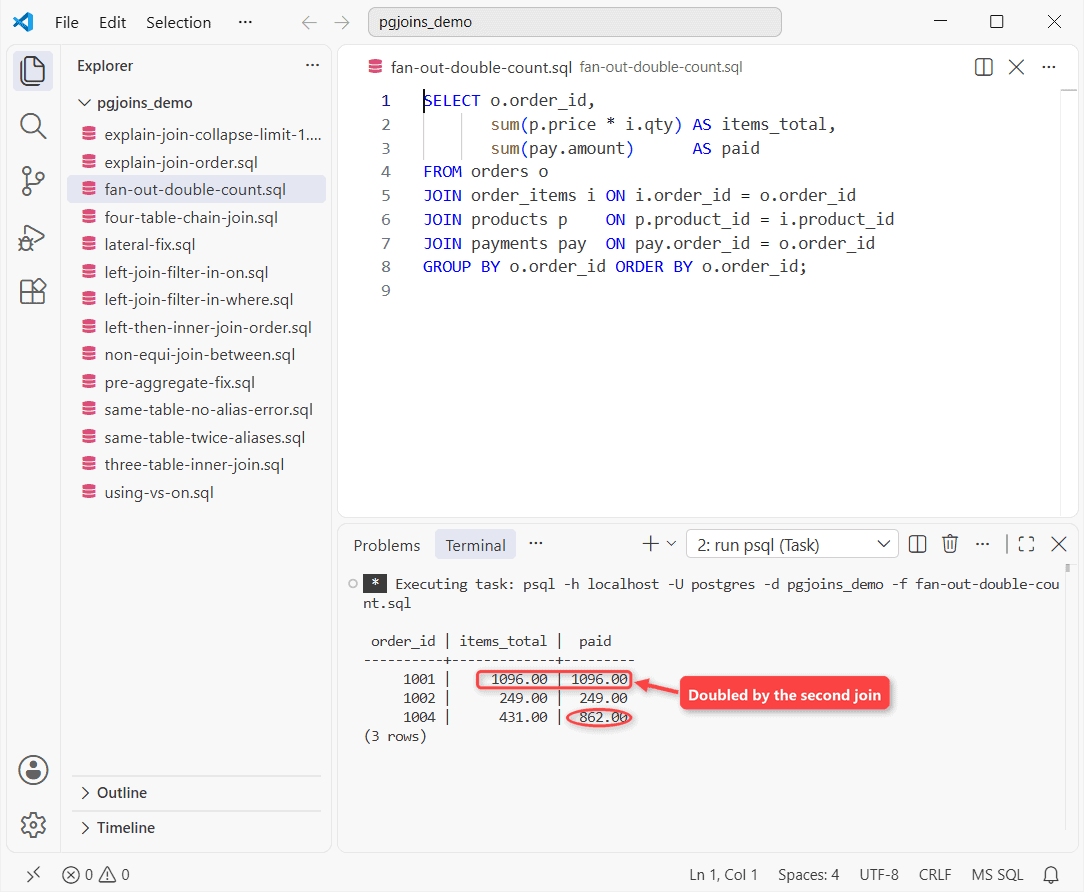
How does this work?
Each item row pairs with each payment row of its order: 2 x 2 = 4 rows for 1001, 2 x 1 = 2 for 1004. SUM adds the duplicates.
Important: DISTINCT inside SUM doesn’t save you, because two different payments can share an amount.
The fix is to aggregate each child to one row per order before joining, using subqueries in FROM:
SELECT o.order_id, it.items_total, pay.paid
FROM orders o
JOIN (SELECT i.order_id, sum(p.price * i.qty) AS items_total
      FROM order_items i JOIN products p USING (product_id)
      GROUP BY i.order_id) it ON it.order_id = o.order_id
JOIN (SELECT order_id, sum(amount) AS paid
      FROM payments GROUP BY order_id) pay
  ON pay.order_id = o.order_id
ORDER BY o.order_id;
Output:
 order_id | items_total |  paid
----------+-------------+--------
     1001 |      548.00 | 548.00
     1002 |      249.00 | 249.00
     1004 |      431.00 | 431.00
(3 rows)
The other option is LATERAL. The subquery can see o.order_id, runs once per order, and returns one row. LEFT JOIN LATERAL ... ON true also keeps unpaid orders 1003 and 1005, with paid = 0:
SELECT o.order_id, it.items_total, coalesce(pay.paid, 0) AS paid
FROM orders o
CROSS JOIN LATERAL (
  SELECT sum(p.price * i.qty) AS items_total
  FROM order_items i JOIN products p USING (product_id)
  WHERE i.order_id = o.order_id) it
LEFT JOIN LATERAL (
  SELECT sum(amount) AS paid FROM payments
  WHERE payments.order_id = o.order_id) pay ON true
ORDER BY o.order_id;
Output:
 order_id | items_total |  paid
----------+-------------+--------
     1001 |      548.00 | 548.00
     1002 |      249.00 | 249.00
     1003 |       84.00 |      0
     1004 |      431.00 | 431.00
     1005 |       79.50 |      0
(5 rows)
I’d pick pre-aggregation for big tables and LATERAL when you need per-row logic, such as the latest payment per order with ORDER BY and LIMIT 1 inside it.
Does join order matter in PostgreSQL? What EXPLAIN ANALYZE shows
For inner joins, the written order barely matters. I wrote this query backward on purpose, starting from order_items, and ran it twice: with the default join_collapse_limit of 8, then with it set to 1.
EXPLAIN (ANALYZE, COSTS OFF, TIMING OFF,
         SUMMARY OFF, BUFFERS OFF)
SELECT c.name, p.name
FROM order_items i
JOIN products p  ON p.product_id = i.product_id
JOIN orders o    ON o.order_id = i.order_id
JOIN customers c ON c.customer_id = o.customer_id
WHERE c.state = 'WA';
Output:
                                    QUERY PLAN
----------------------------------------------------------------------------------
 Nested Loop (actual rows=2.00 loops=1)
   Join Filter: (p.product_id = i.product_id)
   Rows Removed by Join Filter: 2
   ->  Hash Join (actual rows=2.00 loops=1)
         Hash Cond: (i.order_id = o.order_id)
         ->  Seq Scan on order_items i (actual rows=7.00 loops=1)
         ->  Hash (actual rows=1.00 loops=1)
               Buckets: 1024  Batches: 1  Memory Usage: 9kB
               ->  Hash Join (actual rows=1.00 loops=1)
                     Hash Cond: (o.customer_id = c.customer_id)
                     ->  Seq Scan on orders o (actual rows=5.00 loops=1)
                     ->  Hash (actual rows=1.00 loops=1)
                           Buckets: 1024  Batches: 1  Memory Usage: 9kB
                           ->  Seq Scan on customers c (actual rows=1.00 loops=1)
                                 Filter: (state = 'WA'::bpchar)
                                 Rows Removed by Filter: 4
   ->  Seq Scan on products p (actual rows=2.00 loops=2)
(17 rows)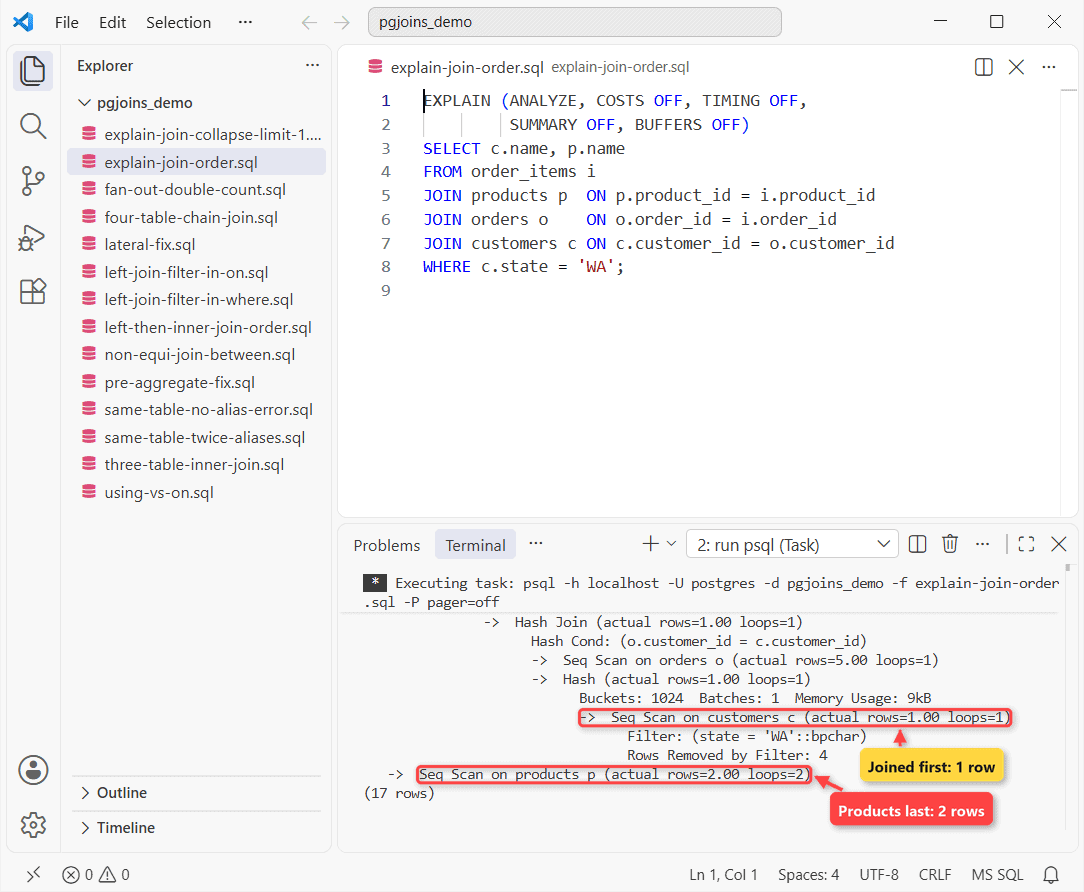
SET join_collapse_limit = 1;
EXPLAIN (ANALYZE, COSTS OFF, TIMING OFF,
         SUMMARY OFF, BUFFERS OFF)
SELECT c.name, p.name
FROM order_items i
JOIN products p  ON p.product_id = i.product_id
JOIN orders o    ON o.order_id = i.order_id
JOIN customers c ON c.customer_id = o.customer_id
WHERE c.state = 'WA';
Output with join_collapse_limit = 1:
SET
                                QUERY PLAN
---------------------------------------------------------------------------
 Hash Join (actual rows=2.00 loops=1)
   Hash Cond: (o.customer_id = c.customer_id)
   ->  Hash Join (actual rows=7.00 loops=1)
         Hash Cond: (i.order_id = o.order_id)
         ->  Hash Join (actual rows=7.00 loops=1)
               Hash Cond: (i.product_id = p.product_id)
               ->  Seq Scan on order_items i (actual rows=7.00 loops=1)
               ->  Hash (actual rows=4.00 loops=1)
                     Buckets: 1024  Batches: 1  Memory Usage: 9kB
                     ->  Seq Scan on products p (actual rows=4.00 loops=1)
         ->  Hash (actual rows=5.00 loops=1)
               Buckets: 1024  Batches: 1  Memory Usage: 9kB
               ->  Seq Scan on orders o (actual rows=5.00 loops=1)
   ->  Hash (actual rows=1.00 loops=1)
         Buckets: 1024  Batches: 1  Memory Usage: 9kB
         ->  Seq Scan on customers c (actual rows=1.00 loops=1)
               Filter: (state = 'WA'::bpchar)
               Rows Removed by Filter: 4
(18 rows)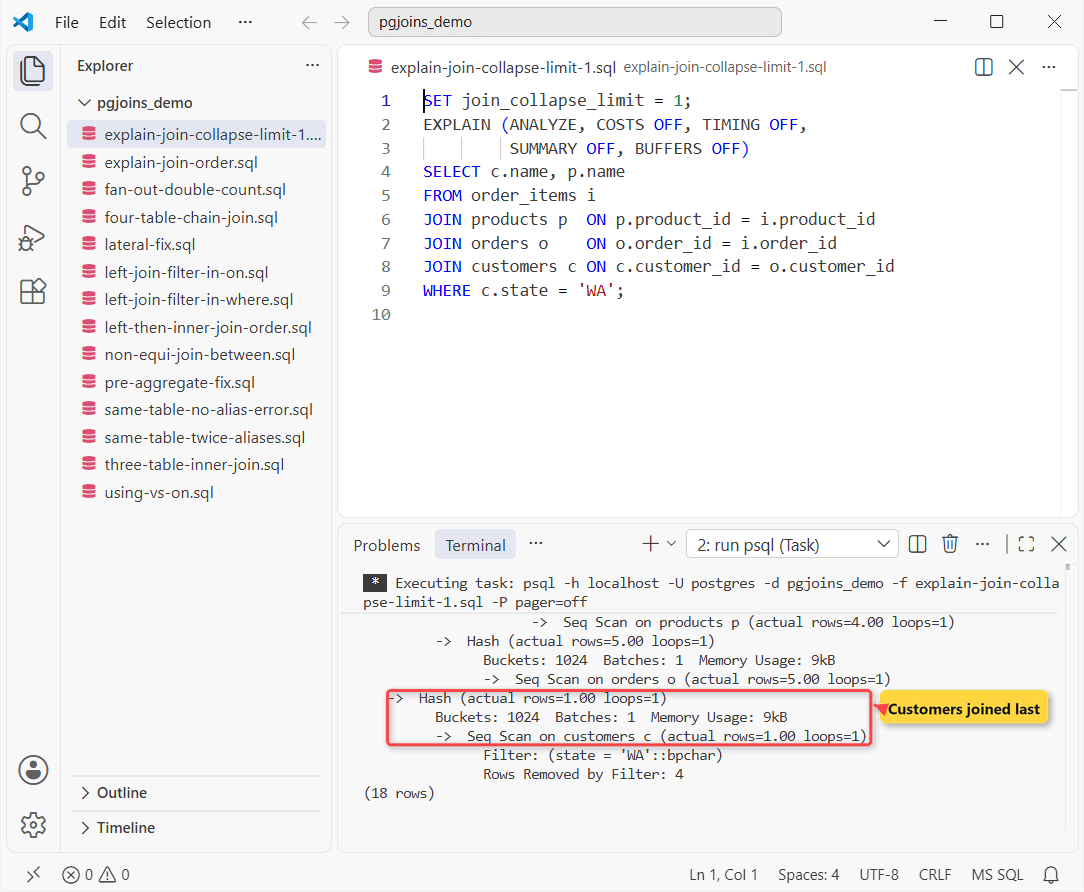
How does this work?
With the default, the planner ignored my FROM order: it filtered customers to the 1 WA row, joined orders, and only 2 rows ever reached products. At join_collapse_limit = 1 it followed the text and pushed all 7 item rows through two joins before filtering.
On six tiny tables both finish instantly, so I’m not quoting timings. The shape is the point: hand-ordering a pure INNER JOIN chain rarely helps.
Where the answer flips
The planner only reorders inner joins freely. FULL JOIN fixes the order completely, and LEFT JOIN restricts it.
Past 8 explicit joins the planner stops flattening them, so a 10-table query keeps part of your written order. Index the join keys too; creating an index in PostgreSQL covers that.
Which multiple-join pattern should you use?
| You need | Use |
|---|---|
| Rows that match in every table | chained INNER JOINs, any order |
| Every row from the first table, matches optional | LEFT JOIN for each optional table, filters in ON |
| The same table in two roles | two aliases (rep, mgr) |
| Totals from two one-to-many tables | pre-aggregate each, or LATERAL |
| Matching column names, short chain | USING |
Things to Keep in Mind
- Qualify every column with its alias once three tables are involved; a later ALTER TABLE can make a bare name ambiguous (42702).
- Count rows after each JOIN you add while building the query. A jump means fan-out or a missing ON.
- Run ANALYZE after a bulk load; join order choices depend on row estimates.
- UPDATE and DELETE use FROM/USING instead of JOIN: see PostgreSQL UPDATE with JOIN.
Next step: wrap a multi-join query you reuse in a PostgreSQL view. Also worth a look:
Frequently Asked Questions
How many tables can you join in one PostgreSQL query?
There’s no small fixed limit. At 12 or more FROM items (geqo_threshold) the planner switches to a genetic search instead of trying every join order.
Is JOIN the same as INNER JOIN in PostgreSQL?
Yes. INNER is the default join type, so plain JOIN is an inner join. LEFT JOIN and LEFT OUTER JOIN are also identical.
Is a comma-separated FROM list the same as INNER JOIN?
For the planner, yes, but JOIN binds tighter than the comma, so an ON can’t see a table listed before the comma (table expressions).
How do I force PostgreSQL to join tables in my written order?
Run SET join_collapse_limit = 1 in the session; the planner then follows your explicit JOINs (controlling the planner).
Kumar Saurabh is a freelance software engineer who builds web and mobile apps with Next.js, React, Flutter and Python. From 2021 to 2024, Saurabh worked as an IT analyst and developer at TSInfo Technologies, writing technical articles on SQL and PostgreSQL. Saurabh writes the PostgreSQL, MySQL, MariaDB and MongoDB tutorials on DatabaseFAQs.com and holds a Master of Computer Applications (MCA) from Chandigarh University.