
If you’ve tried ORDER BY ship_date DESC to find your latest shipment, you’ve probably seen blank dates land on top. PostgreSQL ORDER BY sorts rows by any column or expression; add NULLS LAST and those blanks drop to the bottom.
Without ORDER BY, PostgreSQL returns rows in no guaranteed order, so every “top N” or “newest” query you write needs one.
In this tutorial, I’ll walk you through PostgreSQL ORDER BY on one small orders table: ASC and DESC, multiple columns, NULLs, LIMIT, dates, custom lists, counts, UNION, arrays and collations.
The sample orders table we’ll use
I ran everything on PostgreSQL 18 in a demo database, dfq_pgorderby:
CREATE TABLE orders (
  order_id   int PRIMARY KEY,
  customer   varchar(20),  state char(2),  status varchar(12),
  amount     numeric(10,2),
  ordered_at timestamp(0),
  ship_date  date            -- NULL until the order ships
);
It holds eight October 2026 orders. Watch the ties (two $249.00 orders, two placed at 8:30 AM on 10/22/2026) and four NULL ship dates.
Want your own copy? Here’s how to create a table in PostgreSQL.
PostgreSQL ORDER BY ASC and DESC
ORDER BY goes last in a PostgreSQL SELECT. ASC is the default; DESC puts the biggest value first:
SELECT customer, amount
FROM orders
ORDER BY amount DESC
LIMIT 3;
Output:
    customer    | amount
----------------+--------
 Lidia Holloway | 412.30
 Adele Vance    | 249.00
 Megan Bowen    | 249.00
(3 rows)
Lidia’s $412.30 is first, but the two $249.00 rows can swap between runs: nothing breaks their tie.
ORDER BY multiple columns
List the columns with commas, each with its own direction. Same orders table (CA and TX), by state, then biggest amount:
SELECT state, customer, amount
FROM orders
WHERE state IN ('CA', 'TX')
ORDER BY state ASC, amount DESC;
Output:
 state |    customer     | amount
-------+-----------------+--------
 CA    | Isaiah Langer   | 132.00
 CA    | Alex Wilber     |  89.50
 TX    | Megan Bowen     | 249.00
 TX    | Diego Siciliani |  89.50
 TX    | Lee Gu          |  15.75
(5 rows)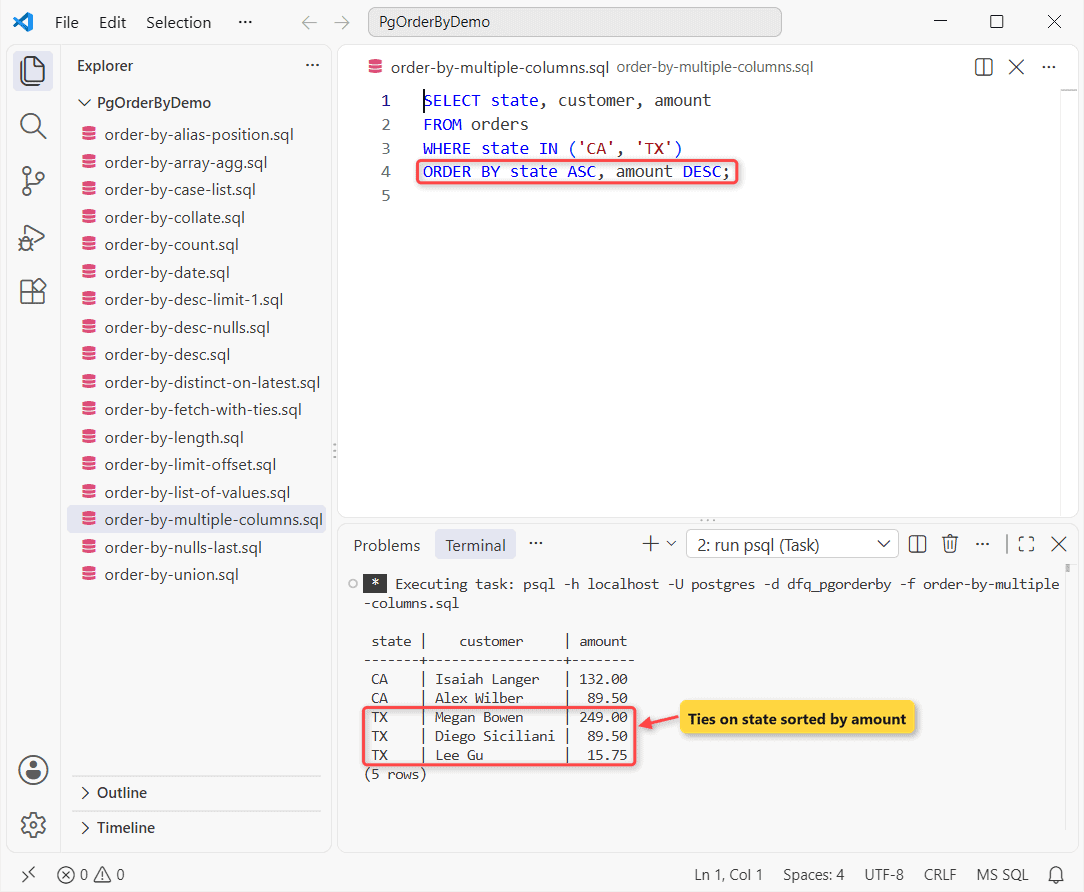
How does this work?
PostgreSQL sorts by state and uses amount only to break ties, so TX lists Megan, Diego, then Lee. DESC applies only to the column it follows.
How does PostgreSQL sort NULLs? NULLS FIRST and NULLS LAST
NULL sorts as if it’s larger than any value: last in ASC, first in DESC. Same orders, latest ship date:
SELECT order_id, ship_date FROM orders
ORDER BY ship_date DESC
LIMIT 3;
Output:
 order_id | ship_date
----------+-----------
      102 |
      104 |
      105 |
(3 rows)
SELECT order_id, ship_date FROM orders
ORDER BY ship_date DESC NULLS LAST
LIMIT 3;Output:
 order_id | ship_date
----------+------------
      106 | 2026-10-24
      107 | 2026-10-17
      103 | 2026-10-06
(3 rows)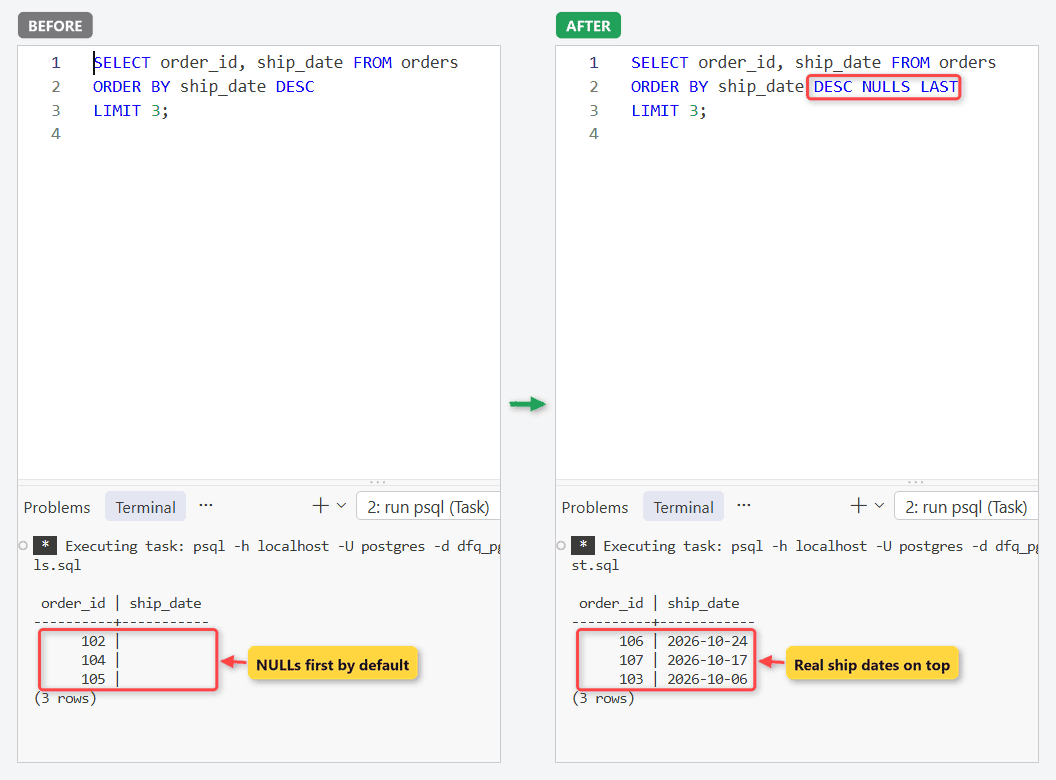
How does this work?
Plain DESC gives you three unshipped orders. NULLS LAST overrides the default, so 10/24/2026 comes first. NULLS FIRST does the opposite in an ASC sort.
ORDER BY a column alias or column position
You can sort by an output alias or a SELECT-list position. Same table, with 8.25% sales tax:
SELECT customer, amount * 1.0825 AS with_tax
FROM orders
ORDER BY with_tax DESC
LIMIT 2;

SELECT customer, amount FROM orders ORDER BY 2, 1 LIMIT 2;

SELECT customer, amount * 1.0825 AS with_tax
FROM orders
ORDER BY with_tax + 0;
Output and error:
    customer    |  with_tax
----------------+------------
 Lidia Holloway | 446.314750
 Megan Bowen    | 269.542500
(2 rows)

    customer    | amount
----------------+--------
 Lee Gu         |  15.75
 Johanna Lorenz |  64.99
(2 rows)

psql:order-by-alias-position.sql:10: ERROR:  column "with_tax" does not exist
LINE 3: ORDER BY with_tax + 0;
                 ^
The alias and ORDER BY 2, 1 work; an alias inside an expression fails, so repeat the expression.
Important: I keep positions to ad hoc queries. They break when someone reorders the SELECT list.
PostgreSQL ORDER BY with LIMIT, OFFSET and FETCH FIRST
LIMIT keeps the first N sorted rows and OFFSET skips rows. Here’s page 2 at three rows per page:
SELECT order_id, customer
FROM orders
ORDER BY order_id
LIMIT 3 OFFSET 3;
Output:
 order_id |    customer
----------+-----------------
      104 | Lee Gu
      105 | Lidia Holloway
      106 | Diego Siciliani
(3 rows)
Sort pages on a unique column, or rows can repeat or vanish.
Keep ties with FETCH FIRST … WITH TIES
Same orders, top two amounts. LIMIT 2 would drop one $249.00 order at random:
SELECT customer, amount
FROM orders
ORDER BY amount DESC
FETCH FIRST 2 ROWS WITH TIES;
Output:
    customer    | amount
----------------+--------
 Lidia Holloway | 412.30
 Adele Vance    | 249.00
 Megan Bowen    | 249.00
(3 rows)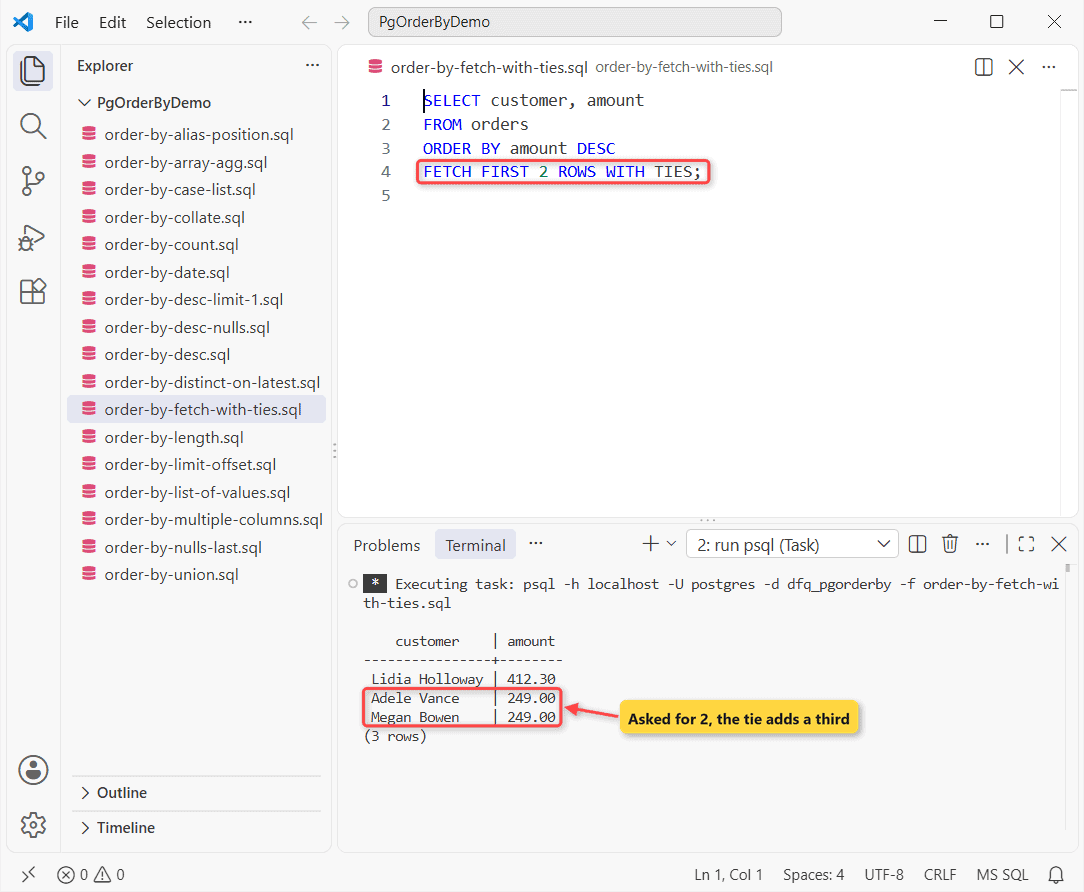
WITH TIES (PostgreSQL 13+) needs ORDER BY and adds every row tied with the last one, like a RANK() filter.
PostgreSQL ORDER BY DESC LIMIT 1: get the newest row
Sort the timestamp DESC and keep one row. Same orders: 105 and 106 share the same timestamp.
SELECT order_id, customer, ordered_at
FROM orders
ORDER BY ordered_at DESC, order_id DESC
LIMIT 1;
Output:
 order_id |    customer     |     ordered_at
----------+-----------------+---------------------
      106 | Diego Siciliani | 2026-10-22 08:30:00
(1 row)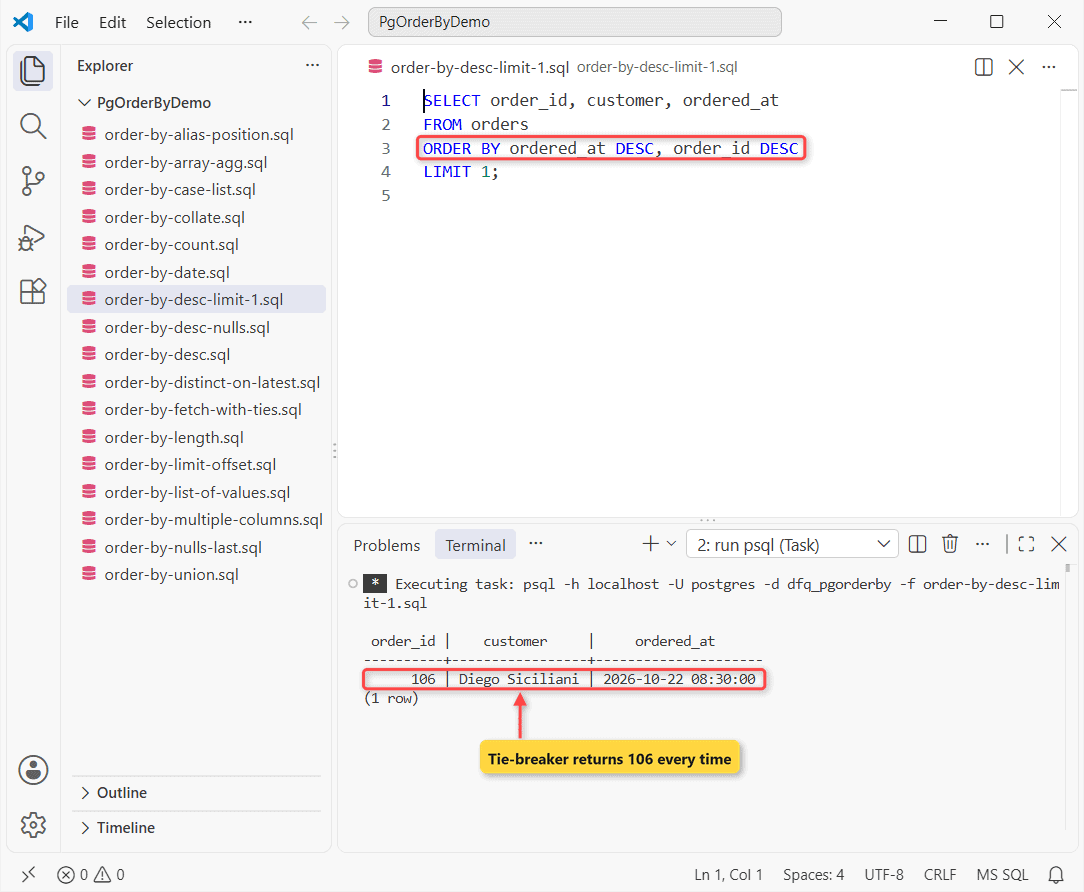
For the newest row per state, DISTINCT ON does it in one pass:
SELECT DISTINCT ON (state) state, order_id, ordered_at
FROM orders
ORDER BY state, ordered_at DESC, order_id DESC;
Output:
 state | order_id |     ordered_at
-------+----------+---------------------
 CA    |      107 | 2026-10-15 10:20:00
 CO    |      108 | 2026-10-18 13:45:00
 NY    |      105 | 2026-10-22 08:30:00
 TX    |      106 | 2026-10-22 08:30:00
 WA    |      103 | 2026-10-03 16:40:00
(5 rows)
How does this work?
order_id DESC breaks the tie, so you always get 106. DISTINCT ON (state) keeps each state’s first row, so its ORDER BY must start with state. For top 3 per group, use ROW_NUMBER().
PostgreSQL ORDER BY date and timestamp
Date and timestamp columns sort chronologically. Here I sort by day, then amount, and fix dates stored as text:
SELECT order_id, ordered_at::date AS day, amount
FROM orders
ORDER BY ordered_at::date DESC, amount DESC
LIMIT 3;

SELECT d AS text_date FROM (VALUES ('10/12/2026'),
  ('9/30/2026'), ('10/3/2026')) AS v(d)
ORDER BY to_date(d, 'MM/DD/YYYY');
Output:
 order_id |    day     | amount
----------+------------+--------
      105 | 2026-10-22 | 412.30
      106 | 2026-10-22 |  89.50
      108 | 2026-10-18 |  64.99
(3 rows)

 text_date
------------
 9/30/2026
 10/3/2026
 10/12/2026
(3 rows)
Both 10/22/2026 orders share a day, so $412.30 leads. Text dates sort wrong (’10/12′ before ‘9/30’); to_date() fixes that. For months, sort by date_trunc(‘month’, ordered_at).
ORDER BY length of a string
Sort by any expression. Same customers, shortest name first:
SELECT customer, length(customer) AS chars
FROM orders
ORDER BY length(customer), customer
LIMIT 3;
Output:
  customer   | chars
-------------+-------
 Lee Gu      |     6
 Adele Vance |    11
 Alex Wilber |    11
(3 rows)
length() counts characters, and customer breaks the tie at 11. Details in my PostgreSQL length() guide.
ORDER BY a list of values (custom sort order)
Status values don’t sort usefully A to Z. Same orders table, your own order:
SELECT status, count(*) AS orders
FROM orders
GROUP BY status
ORDER BY array_position(
  ARRAY['Pending','Backordered','Shipped','Canceled'], status);
Output:
   status    | orders
-------------+--------
 Pending     |      2
 Backordered |      1
 Shipped     |      4
 Canceled    |      1
(4 rows)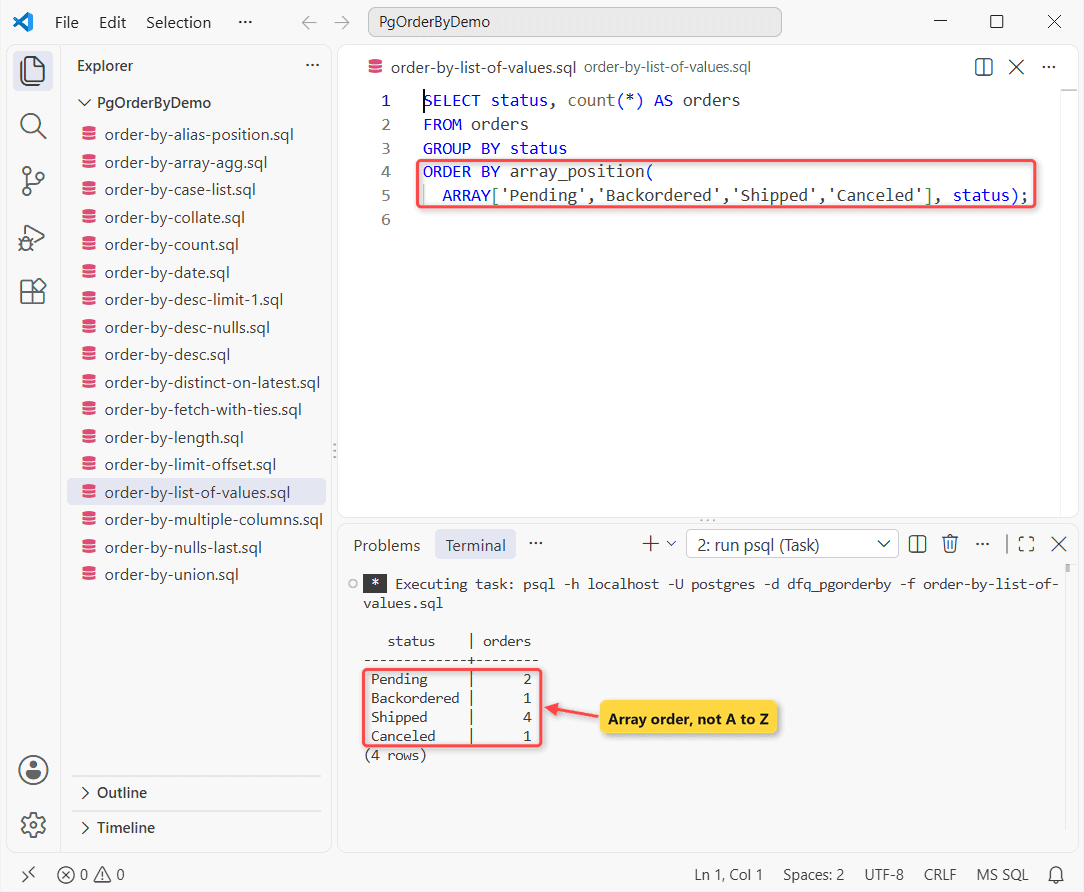
How does this work?
array_position() returns each status’s place in the array, and values not in it sort last. A CASE expression does the same, here for IDs 108, 101, 105:
SELECT order_id, status FROM orders
WHERE order_id IN (108, 101, 105)
ORDER BY CASE order_id WHEN 108 THEN 1 WHEN 101 THEN 2 ELSE 3 END;
Output:
 order_id |   status
----------+-------------
      108 | Backordered
      101 | Shipped
      105 | Pending
(3 rows)
PostgreSQL ORDER BY count with GROUP BY
Same orders, counted per state. Sort by the alias or by count(*) itself:
SELECT state, count(*) AS orders, sum(amount) AS total
FROM orders
GROUP BY state
ORDER BY orders DESC, total DESC;
Output:
 state | orders | total
-------+--------+--------
 TX    |      3 | 354.25
 CA    |      2 | 221.50
 NY    |      1 | 412.30
 WA    |      1 | 249.00
 CO    |      1 |  64.99
(5 rows)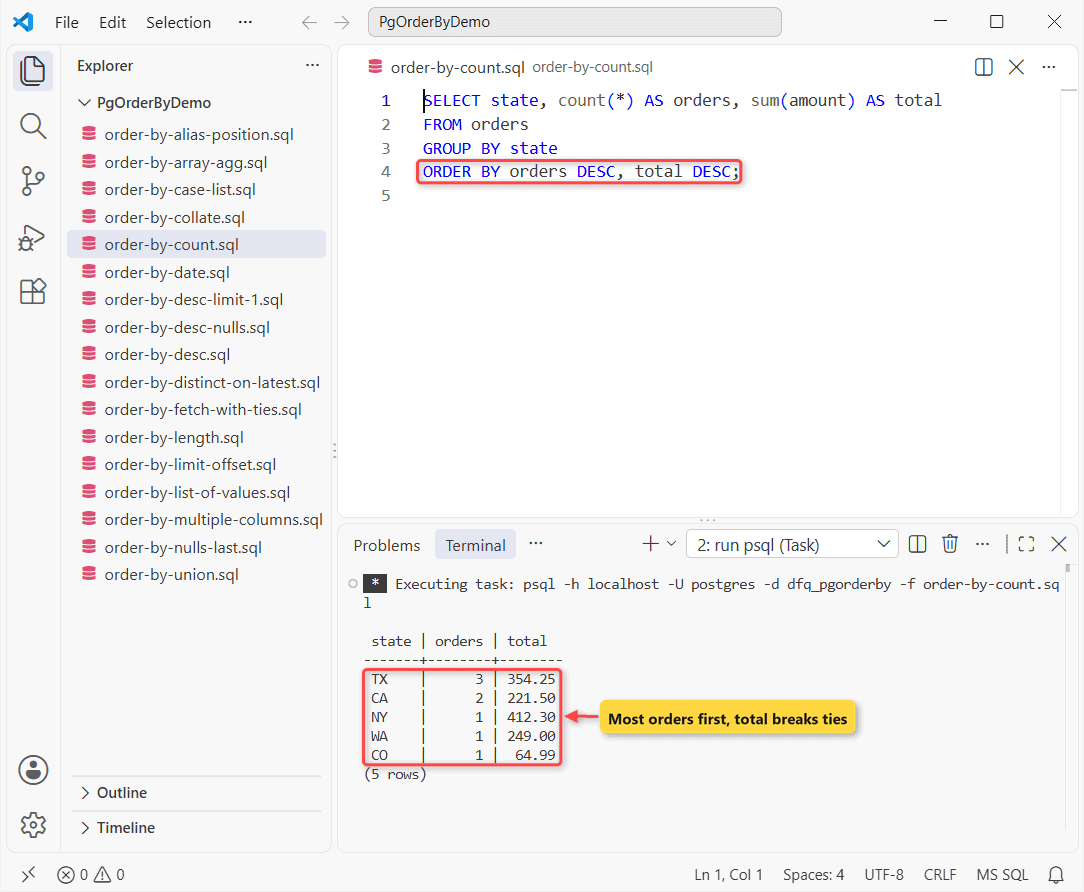
How does this work?
GROUP BY makes one row per state, then ORDER BY sorts them. total DESC orders the one-order states.
ORDER BY with UNION
A final ORDER BY sorts the whole UNION. Parentheses sort and limit one branch. Same orders plus two returns:
SELECT 'order' AS kind, customer, amount
FROM orders WHERE state = 'TX'
UNION ALL
SELECT 'return', customer, amount FROM returns
ORDER BY amount DESC;

(SELECT customer, amount FROM orders ORDER BY amount DESC LIMIT 1)
UNION ALL
(SELECT customer, amount FROM returns ORDER BY amount DESC LIMIT 1);

SELECT customer, amount FROM orders UNION ALL
SELECT customer, amount FROM returns ORDER BY abs(amount);
Output and error:
  kind  |    customer     | amount
--------+-----------------+--------
 order  | Megan Bowen     | 249.00
 order  | Diego Siciliani |  89.50
 return | Megan Bowen     |  49.00
 order  | Lee Gu          |  15.75
 return | Lee Gu          |  15.75
(5 rows)

    customer    | amount
----------------+--------
 Lidia Holloway | 412.30
 Megan Bowen    |  49.00
(2 rows)

psql:order-by-union.sql:12: ERROR:  invalid UNION/INTERSECT/EXCEPT ORDER BY clause
LINE 2: SELECT customer, amount FROM returns ORDER BY abs(amount);
                                                      ^
DETAIL:  Only result column names can be used, not expressions or functions.
HINT:  Add the expression/function to every SELECT, or move the UNION into a FROM clause.
A UNION’s ORDER BY accepts only output column names or numbers. For abs(amount), wrap the UNION in a subquery.
Order array contents with array_agg(… ORDER BY)
ORDER BY inside an aggregate sets the element order. Same orders, customers per state, newest first:
SELECT state,
       array_agg(customer ORDER BY ordered_at DESC) AS newest_first
FROM orders
GROUP BY state
HAVING count(*) > 1
ORDER BY state;

SELECT array(SELECT unnest(ARRAY[31, 9, 16]) ORDER BY 1) AS sorted;
Output:
 state |                newest_first
-------+--------------------------------------------
 CA    | {"Isaiah Langer","Alex Wilber"}
 TX    | {"Diego Siciliani","Lee Gu","Megan Bowen"}
(2 rows)

  sorted
-----------
 {9,16,31}
(1 row)
To sort an existing array, unnest it and rebuild it. string_agg() takes ORDER BY too.
Why ORDER BY sorts text differently: COLLATE “C” vs en-US
Text follows the column’s collation; COLLATE overrides it per query:
SELECT name FROM (VALUES ('megan'), ('Alex'), ('adele'), ('Megan')) AS v(name)
ORDER BY name COLLATE "C";

SELECT name FROM (VALUES ('megan'), ('Alex'), ('adele'), ('Megan')) AS v(name)
ORDER BY name COLLATE "en-US-x-icu";
Output:
 name
-------
 Alex
 Megan
 adele
 megan
(4 rows)

 name
-------
 adele
 Alex
 megan
 Megan
(4 rows)
“C” compares bytes, so capitals come first. ICU en-US-x-icu sorts like a dictionary (libc on Linux calls it "en_US"). To filter without case, use ILIKE.
Which PostgreSQL ORDER BY pattern should you use?
| You need… | Use |
|---|---|
| Newest row | ORDER BY ts DESC, id DESC LIMIT 1 |
| Latest date, NULLs last | DESC NULLS LAST |
| Top N with ties | FETCH FIRST n ROWS WITH TIES |
| Your own value order | array_position(ARRAY[...], col) |
Things to Keep in Mind
- No ORDER BY means no guaranteed order, even if it looks sorted today.
- Add a unique tie-breaker to every LIMIT query.
- Large sorts speed up with an index on the ORDER BY columns.
Want to go further with sorting? You’ll like these:
- Sorting by a JSON field
- Filtering rows before you sort them
- PostgreSQL date functions
- Filtering groups with HAVING
Frequently Asked Questions
What is the default sort order of ORDER BY in PostgreSQL?
ASC, with NULLs last; with DESC, NULLs come first (PostgreSQL 18 sorting docs).
How do I get the last record in PostgreSQL?
Sort by your timestamp or ID descending, add LIMIT 1, and use the primary key as a tie-breaker.
How do I order by multiple columns in different directions?
Give each column its own ASC or DESC, like ORDER BY state ASC, amount DESC. A direction applies only to the column it follows, so ORDER BY state, amount DESC still sorts state ascending.
Does ORDER BY slow down a query?
It can on large tables. A B-tree index on the sort columns lets PostgreSQL skip the sort, especially with LIMIT (SELECT reference).
Kumar Saurabh is a freelance software engineer who builds web and mobile apps with Next.js, React, Flutter and Python. From 2021 to 2024, Saurabh worked as an IT analyst and developer at TSInfo Technologies, writing technical articles on SQL and PostgreSQL. Saurabh writes the PostgreSQL, MySQL, MariaDB and MongoDB tutorials on DatabaseFAQs.com and holds a Master of Computer Applications (MCA) from Chandigarh University.